Which Claude Model Should You Use? Opus, Sonnet and Haiku by Job in 2026
As of October 8, 2026, Claude has four current tiers: Fable 5.1 ($10/$50 per million tokens), Opus 5.5 ($4/$20), Sonnet 5.5 ($2/$10) and Haiku 5.5 ($0.10/$0.50 on prompts up to 100,000 tokens). All four share a 1M context window and a June 2026 knowledge cutoff, so the choice comes down to job difficulty and volume.
The short version
Default to Claude Sonnet 5.5 for coding, writing and research. Use Opus 5.5 for multi-hour agentic work, Fable 5.1 only when Opus falls short on your evals, and Haiku 5.5 for high-volume, latency-sensitive jobs, where it costs $0.10 per million input tokens on prompts up to 100,000 tokens.
Want this decided for your own case? Find your tools with Smart Match, starting from this guide's question.
Claude's lineup changed twice in nine days, and its cheapest tier now costs a tenth of its old price on short prompts. Sonnet 5.5 shipped on September 28, 2026, and Haiku 5.5 followed on October 7, completing the 5.5 family that began with Claude Opus 5.5 on September 22. Haiku 5.5 lists at $0.10 per million input tokens for prompts up to 100,000 tokens.
Claude now ships in four current tiers: Fable 5.1, Opus, Sonnet 5.5 and Haiku. The price steps between them are no longer even. Fable costs 2.5 times what Opus does, Opus costs twice what Sonnet does, and Sonnet costs 20 times what Haiku does on short prompts.
Pick the wrong tier and you either waste money or wait on a model that was never fast enough for the job. This guide sorts the four by the job, not by the launch date, using Anthropic's pricing docs and model comparison table as checked on October 8, 2026.
What Changed Since September 23, 2026
The previous version of this guide listed Sonnet 5 and Haiku 4.5 as the two lower tiers and said Sonnet 5.5 and Haiku 5.5 were weeks away. Both shipped. Each item below was checked against Anthropic's own pages on October 8.
- Sonnet 5.5 replaced Sonnet 5 as the middle tier. The list price held at $2/$10. Anthropic reports 70.6% on Terminal-Bench 4.0, against 10.3% for the older model.
- Haiku 5.5 replaced Haiku 4.5 as the small tier. Context grew from 200,000 to 1M tokens, and the knowledge cutoff moved from February 2025 to June 2026.
- Sonnet 5.5 cache reads got cheaper. Anthropic halved them to $0.10 per million tokens, which it says trims most agentic work on that model by about 20%.
Two corrections matter just as much as the new releases.
- Haiku 4.5 is not retiring on October 15. The earlier version of this guide treated that date as a retirement date. Anthropic's deprecations page lists Haiku 4.5 as active, with no deprecation date and retirement "not sooner than" October 15, 2026. That is a floor, not a schedule.
- The old Sonnet is not gone. Sonnet 5 is still listed as active, with retirement not sooner than June 30, 2027. The top of the lineup held: Fable 5.1 and Opus 5.5 are unchanged.
The migration question for Haiku 4.5 users has its own write-up: Claude Haiku 5.5 vs Haiku 4.5.
How to Choose Between Claude's Four Tiers
Anthropic's own guidance boils the decision down to three questions, before you look at any single benchmark: how capable does the output need to be, how fast does it need to arrive, and what is the budget for the volume involved. A fourth lever most people skip is the effort parameter, which trades intelligence for latency and cost inside a single model rather than forcing a switch to a different one.
The practical version: start efficiency-first with the small tier if the task is high-volume or latency-sensitive, and upgrade only when you hit a specific capability gap. Or start capability-first with Sonnet or Opus, and step down once evals show a cheaper tier holds up.
Either path works. What does not work is picking a tier once, by reputation, and never testing whether a cheaper option is good enough. The vendor's model-selection matrix also says that most workloads start with Opus 5.5. HokAI's default is Sonnet 5.5 instead, for a plain reason: it costs half as much, and the counterargument section below explains when Anthropic's default is the better call.
Combining Models Instead of Picking Just One
Anthropic's own documentation describes a third option that skips the single-model decision entirely: pairing a cheap model with a frontier one so most tokens bill at the lower rate. Anthropic positions its smallest model for exactly this, saying it pairs well with the two larger ones as a subagent on coding work. Two patterns show up most often in production systems built this way.
An executor-advisor pattern uses a fast, cheap model to handle routine steps and escalates only the hard decisions to a frontier model. An orchestrator pattern has a capable model delegate bulk work to a swarm of cheaper workers, then reviews the results. Both cut cost without giving up quality on the parts of the job that need it.
This is worth considering before defaulting to a single tier for an entire application. A support bot, for instance, might run the small tier for the first response and escalate only when a customer's question does not match a known pattern. A coding agent could run the same way: the small tier classifies which files a change touches, the middle tier writes the patch, and Opus only gets called in when a test suite fails and the agent needs to reason about why.
Neither pattern requires locking the whole application to one price point. It requires deciding, task by task, which tier that specific step actually needs.
The Shortlist: All Four Tiers at a Glance
| Model | Price in / out per MTok | Latency | Context |
|---|---|---|---|
| Fable 5.1 | $10 / $50 | Slower | 1M tokens |
| Opus 5.5 | $4 / $20 | Moderate | 1M tokens |
| Sonnet 5.5 | $2 / $10 | Fast | 1M tokens |
| Haiku 5.5 | $0.10 / $0.50 | Fastest | 1M tokens |
All four share a June 2026 knowledge cutoff, a 128,000-token output limit and adaptive thinking, so the old knowledge-cutoff gap between Sonnet and Haiku is gone. The Haiku 5.5 price in the table applies to prompts up to 100,000 tokens. Above that it rises to $0.50 input and $2.50 output, which makes Haiku 5.5 the one current Claude model that does not get the full 1M context at a flat rate.
The quick version, ahead of the job-by-job detail below: default to Sonnet unless you have a specific reason not to.
- Writing, coding, research, most chat work: Sonnet 5.5
- Multi-hour autonomous coding, large refactors, computer-use tasks: Opus 5.5
- Everything you'd give Opus, but it still isn't enough on your own evals: Fable 5.1
- High-volume, latency-sensitive, or genuinely simple tasks with prompts under 100,000 tokens: Haiku 5.5
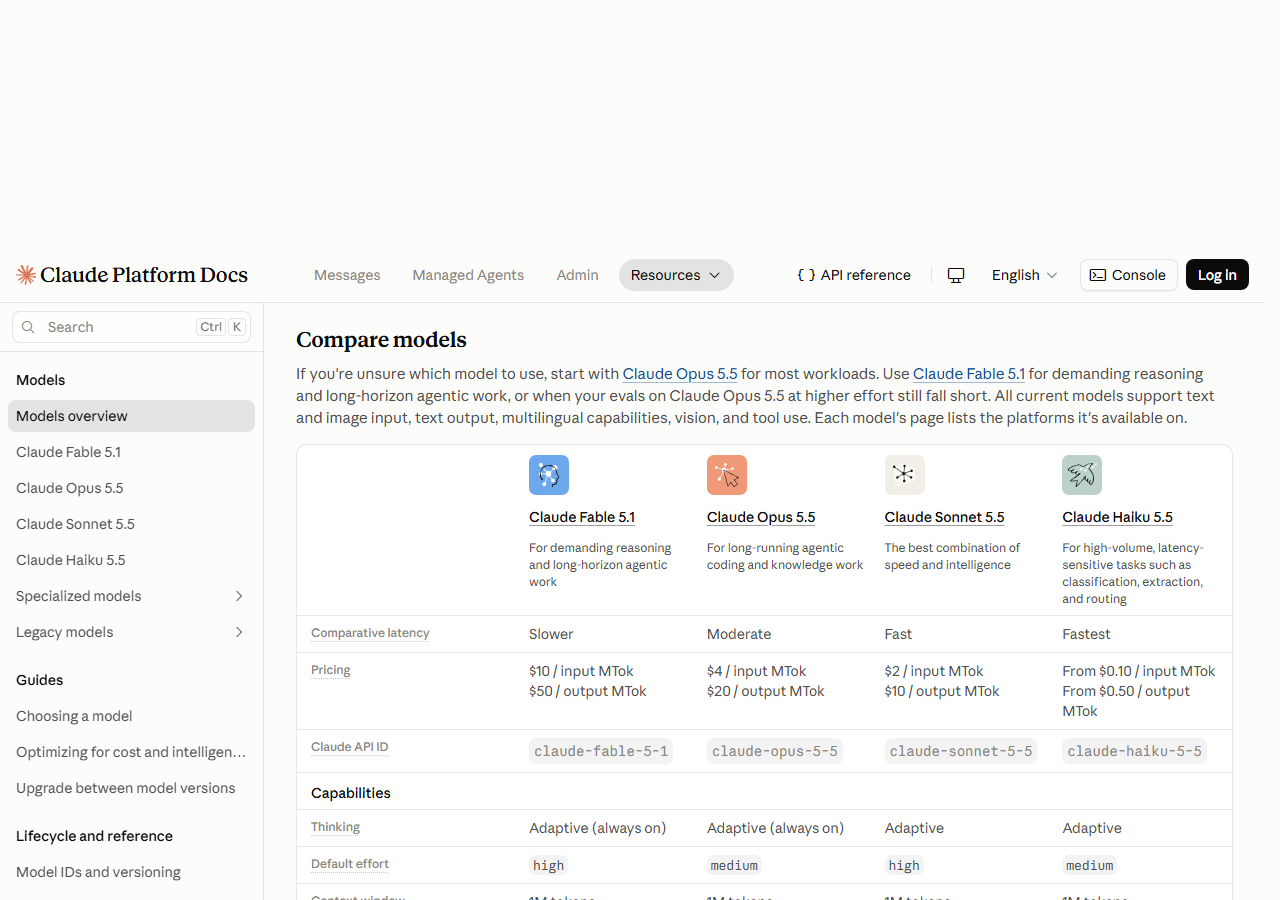 Anthropic's own model comparison table, which lists all four current tiers with latency, pricing and default effort. Captured October 8, 2026.
Which Model for Coding
Anthropic's model-selection matrix puts complex agentic coding and enterprise work under Opus 5.5, with example use cases like multihour autonomous agents and large-scale refactoring. Everyday coding and agentic tool use sits under Sonnet 5.5.
The benchmark gap is narrower than the price gap suggests. Anthropic reports Sonnet 5.5 at 70.6% on Terminal-Bench 4.0, and says that on several evaluations it performs comparably to Opus 5.5 when run at Max effort. Opus 5.5 posts 89.9% on the harder SWE-bench Pro suite, according to its system card. That is a different benchmark, not just a bigger number on the same one.
Haiku sits well below Sonnet on the same agentic coding test, at 39.2% on Terminal-Bench 4.0. The vendor's own reading of that chart is that the two larger models remain the better choices for complex agentic coding, and that Haiku suits narrower, well-scoped work.
For a solo developer or small team working through an editor or CLI, the honest default is Sonnet: fast enough for a real-time loop, and cheap enough that a busy day of tool calls stays affordable. Reach for Opus specifically when a task runs unattended for hours, where a wrong turn three steps in is expensive to unwind.
Windsurf is one example of an editor that lets you swap the underlying model without rewriting your prompts, and HokAI's directory of coding assistants lists more. For a comparison across labs, see this four-way model matchup.
Effort tuning matters here as much as the model choice. Per the comparison table, Sonnet 5.5 and Fable 5.1 default to high effort, while Opus 5.5 and Haiku 5.5 default to medium. Raising Opus 5.5 to a higher setting for a genuinely hard problem, then dropping back down once it is solved, is usually cheaper than staying at the top setting for an entire session.
Which Model for Research and Deep Work
Research splits into two different jobs. Quick lookups and synthesizing a handful of sources are Sonnet territory. On Humanity's Last Exam with tools, Anthropic reports 64.5% for Sonnet 5.5 and 57.4% for Haiku 5.5, a gap of seven points for a price difference of twenty times. That is close enough that spending Opus-tier money on a straightforward question is money left unspent for no gain.
Multistep deep research is different. That is the job the same matrix names for Fable 5.1: research that chains searches, reads full documents and reconciles contradictions across sources for twenty minutes or more, carried through to a finished document.
If the job is closer to fact-checking a claim against academic literature, a dedicated tool like Consensus pairs well with either model, finding sources while Claude does the synthesis. HokAI's deep-research roundup and directory of deep-research tools cover what a research-specific tool can see that a general chat model cannot, and a separate breakdown looks at the same question from the researcher's side rather than the model's.
Which Model for Writing and Editing
For drafting, editing and day-to-day writing, Sonnet is the tier Anthropic itself points to: content creation sits in its row of the selection matrix, with strong reasoning and no flagship pricing. The million-token context window means a full manuscript or a stack of prior drafts fits in one prompt, without the summarization tricks smaller-context models used to require.
The small tier is worth considering only for high-volume, formulaic writing: subject lines, short product blurbs, summaries, or a rough first pass you plan to rewrite. Its price and fastest-in-lineup latency are built for that kind of throughput, not for prose meant to publish unedited. If a writing tool such as Writesonic lets you pick a model, the same logic applies whichever app is making the call, and HokAI's directory of writing assistants covers the options beyond those two.
Which Model for a Resume or Job Application
A resume is short, so the price gap between tiers amounts to a fraction of a cent or a couple of cents either way. Assuming 3,000 tokens in and 1,500 out, a rewrite costs about two cents on Sonnet 5.5 and about a tenth of a cent on Haiku 5.5. The decision should be made on quality, not cost, and that favors the middle tier even for a document this size.
The stronger reasoning shows up in the part of a resume rewrite that actually matters: reframing a job history around the target role's real requirements, rather than restating a job title with better adjectives. Kickresume and Teal are both built specifically for this; HokAI's resume-building roundup and directory of resume builders compare the full set against real ATS-parsing behavior.
Which Model for an Always-On Agent
The autocomplete data behind this guide surfaced a specific real question: which model to run behind OpenClaw, the self-hosted agent that connects to WhatsApp, Telegram and other chat apps and keeps running in the background on your own machine. OpenClaw is explicitly model-agnostic. Its own site says to bring hosted, subscription-backed, gateway or local models.
For an agent that sits idle most of the day and then has to plan a multi-step task on short notice, Sonnet is the sensible default. It is inexpensive enough to run continuously and fast enough for the tool-calling loop the framework depends on. Haiku is now cheap enough to handle the background checks and message triage that never need deep planning, while Opus takes individual steps that need deeper reasoning, instead of routing every check through the pricier tier.
Enterprise platforms follow the same math at larger scale. Sierra, which builds AI agents for customer service, faces the identical tradeoff between a fast default model and an escalation path for the harder cases. HokAI's agentic AI roundup covers this job-first logic across tools that aren't tied to one model provider.
When Even Opus Isn't Enough: Fable 5.1
Fable 5.1 is not simply a bigger Opus. Anthropic's docs name it specifically for when evals on Opus 5.5 at higher effort still fall short on demanding reasoning or long-horizon agentic work, and it extends the earlier Fable 5 at the same input and output prices, with cache reads at a quarter of the cost.
At $10 input and $50 output per million tokens, it costs 2.5 times what Opus 5.5 does. That is why Anthropic treats it as a last step, not a starting point: implement with Opus, optimize the prompt, evaluate, and only move up if the evaluation still misses the bar.
The premium does not win everywhere. On Terminal-Bench 4.0, an agentic coding benchmark, Opus 5.5 actually scored higher than Fable 5.1 at launch: 66.4% against 55.8%, according to SiliconANGLE's coverage of Anthropic's own release figures. A higher price is no guarantee of a higher score, which is the whole argument for testing rather than assuming.
Haiku 5.5 or Haiku 4.5: Do You Migrate?
The older model is still active, so nothing forces a move today. The case for moving is mostly price. Anthropic says the new model costs 90% less for requests up to 100,000 tokens and 50% less above that, and that about 90% of Haiku 4.5 requests fell into the shorter bucket. Its own estimate, which also accounts for how many tokens a given piece of work takes, is roughly 75% cheaper on average.
Two caveats keep that from being free money. Haiku 5.5 uses the newer tokenizer, so the same text counts as about 30% more tokens than on Haiku 4.5, and a like-for-like job saves less than the list ratio suggests. And the cheap rate stops at 100,000 tokens of prompt: a long-document workload pays the higher rate above that line, still a quarter of Sonnet's price but not the headline figure.
On the agentic coding test in Anthropic's launch table, Haiku 5.5 scores 39.2% on Terminal-Bench 4.0, while Haiku 4.5 scores 0.0%. Teams on Haiku 4.5 should re-run their own evals, then follow the steps in the Haiku 5.5 vs Haiku 4.5 migration guide.
What Each Tier Costs, With a Worked Example
Anthropic's pricing docs include a worked example that makes the gap concrete, though it is written for Claude Managed Agents on the older Opus 5. A one-hour coding session using 50,000 input tokens and 15,000 output tokens comes to $0.705 there, including an $0.08 session-runtime charge.
With 40,000 of those input tokens served from cache, Anthropic's figure drops to $0.525.
At Opus 5.5's current rates the same token counts cost $0.50 without caching and about $0.35 with it, before any runtime charge. That is HokAI's arithmetic from the published rate card, not an Anthropic figure.
The same math for a lighter, high-volume job shows why the small tier matters. Take 10,000 support tickets at 3,000 input tokens and 700 output tokens each, an assumed split and not a measured one:
| Model | Cost for 10,000 tickets | Multiple of Haiku 5.5 |
|---|---|---|
| Fable 5.1 | $650 | 100x |
| Opus 5.5 | $260 | 40x |
| Sonnet 5.5 | $130 | 20x |
| Haiku 5.5 | $6.50 | 1x |
The previous Haiku would have cost $65 for the same batch at its old list price. Allowing for Haiku 5.5's tokenizer counting about 30% more tokens, the like-for-like Haiku 5.5 bill is closer to $8.45. List prices per million tokens, as of October 8, 2026:
| Model | Input | Output | Cache read |
|---|---|---|---|
| Fable 5.1 | $10 | $50 | $0.25 |
| Opus 5.5 | $4 | $20 | $0.20 |
| Sonnet 5.5 | $2 | $10 | $0.10 |
| Haiku 5.5 (prompts to 100K) | $0.10 | $0.50 | $0.01 |
| Haiku 5.5 (prompts over 100K) | $0.50 | $2.50 | $0.05 |
Five-minute cache writes cost 1.25 times the input price on every model in the table, and the Batch API takes 50% off input and output.
Opus also has a fast mode in research preview, at $8 input and $40 output per million tokens, for up to 2.5x higher output speed on the API only. If you are still running Opus 4.8, the price cut alone is reason to re-run your existing evals against 5.5 before renewing any volume commitment.
Who Should Skip Opus and Fable Entirely
Anthropic's own efficiency-first path exists for a reason. For high-volume, straightforward tasks and tight-latency applications, starting with Haiku and upgrading only on a proven capability gap is the recommended approach, not a compromise.
- Classification and tagging at scale
- Simple extraction from structured text
- High-throughput pipelines where speed matters more than nuance
- Cost-sensitive deployments already validated against real evals
The price difference compounds fast at volume. The ticket batch that costs $6.50 on Haiku 5.5 runs 20 times higher on Sonnet 5.5 and 40 times higher on Opus 5.5, for accuracy gains a straightforward classification task is unlikely to need.
The Case for Starting With Opus Anyway
The strongest argument against everything above comes from the vendor itself: its selection matrix says most workloads start with Opus 5.5, and its capability-first path is to implement with Opus from day one, then downgrade once evals prove a cheaper tier holds up. For a small team without time to build a proper evaluation set, that is not an unreasonable shortcut.
Guessing that a cheaper tier is good enough, and shipping it untested, is how quality regressions reach production quietly. The docs are explicit that tuning the effort parameter, not switching models, is usually the better first lever if a workload feels slow or expensive.
Both paths converge on the same requirement: real evals, not intuition, deciding whether to move. Start wherever matches your actual constraint, and let testing do the rest of the work.
Neither approach is free to skip. A team that starts capability-first and never revisits the choice ends up paying Opus prices for Haiku-shaped work a year later. A team that starts efficiency-first and never re-tests as the job grows ends up shipping a support bot that confidently gets the hard 10% of tickets wrong. The failure mode on both sides is the same: treating the first model chosen as a permanent decision instead of a hypothesis to keep checking.
Data Handling: Does Claude Train on What You Send It?
A separate but common question sits underneath all of this. Anthropic's privacy center states that by default, inputs and outputs from commercial products, including the API and Claude for Work, are not used to train its models. That changes only if you report feedback, for example with the thumbs up or down button, or otherwise choose to allow it.
Consumer app usage, meaning the free, Pro and Max plans at claude.ai, runs under a separate policy. A work task run through the consumer app is not automatically covered by the same commercial-product default, so the distinction matters if the job involves anything sensitive.
Regulated teams have one more knob worth knowing about. On Claude 4.6 and later models, including every tier in this guide, pinning inference to inference_geo: "us" keeps processing inside the United States for a 1.1x price premium across every pricing category. Global routing, the default, uses standard pricing and does not guarantee where a given request is processed. Neither option changes the training policy above; it only changes where the computation physically happens, which is a separate axis entirely from what gets logged or retained.
What Would Change This Answer
Three things could date this guide. The first is a Haiku 4.5 deprecation notice. Until Anthropic posts one, the model stays active, and October 15, 2026 is only the earliest it could retire. Anyone building production infrastructure on Haiku 4.5 should still plan a migration rather than assume the model ID stays pinned indefinitely.
The second is Haiku 5.5's tiered pricing: if Anthropic moves the 100,000-token line, the small-tier math above moves with it. The third is the family itself. Fable 5.1 has a sibling most readers will never touch: Mythos 5.1, the same capability set restricted to participants in Anthropic's Project Glasswing program, priced identically but not generally available.
Retirement dates for the current tiers sit a year or more out. Anthropic lists Sonnet 5.5 as not retiring sooner than September 28, 2027, and Haiku 5.5 as not sooner than October 7, 2027.
If none of the four tiers feels like a confident fit, comparing against every model on the market is worth the extra ten minutes. HokAI's model recommender and full model leaderboard rank every GA model by price, benchmark score and speed side by side. For the vendor behind the models, see Anthropic and its Claude app. OpenAI's cheaper rival models are GPT-6 Luna and GPT-6 Sol.
For a broader look across every frontier lab, not just Anthropic, HokAI's guide to choosing the right LLM lines Fable 5.1 up against GPT-6 Astra, Gemini and DeepSeek's current releases, and how to choose an AI assistant covers the app side of the same decision. What Claude is for explains the product itself. Smart Match will ask about your actual constraints and suggest a shortlist instead of a single guess.
The pattern underneath all four tiers holds even as the names change: pay for reasoning depth only on the fraction of a workload that actually needs it, and let the job, not the launch date, decide which model to open.
Frequently asked questions
Which Claude model should I use for coding?
Sonnet 5.5 for everyday coding and agentic tool use; Anthropic reports 70.6% on Terminal-Bench 4.0 at $2/$10 per million tokens. Reach for Opus 5.5 (89.9% on SWE-bench Pro) for multi-hour autonomous refactors or systems work where an unattended run needs more reliability than speed.
Is Claude Opus 5.5 worth the extra cost over Sonnet 5.5?
Only for jobs Anthropic itself scopes to Opus: long-running agentic coding, computer-use automation, and enterprise workloads where reliability over hours matters more than the 2x price gap. Anthropic says Sonnet 5.5 at Max effort is comparable to Opus 5.5 on several evaluations, so test Sonnet first.
What is Claude Fable 5.1 and when should I use it instead of Opus?
Fable 5.1 is Anthropic's tier above Opus 5.5, priced at $10/$50 per million tokens, built for demanding reasoning and long-horizon agentic work. Anthropic's own guidance says to move to it only after evaluations on Opus 5.5 at higher effort still fall short, not as a default starting point.
Is Claude Haiku 5.5 good enough for production use?
Yes for high-volume, latency-sensitive or narrow tasks like classification, extraction, summaries and routing, at $0.10/$0.50 per million tokens on prompts up to 100,000 tokens. Above that line it costs $0.50/$2.50, and on agentic coding it trails Sonnet 5.5: 39.2% against 70.6% on Terminal-Bench 4.0. Haiku 4.5 is still active, with retirement listed as not sooner than October 15, 2026.
Which Claude model should I use with OpenClaw or a similar AI agent?
Sonnet 5.5 as the default planning model, since OpenClaw and similar self-hosted agent runtimes are model-agnostic and run continuously: its price and speed suit an always-on tool-calling loop. Hand background checks to Haiku 5.5 and escalate specific sub-tasks to Opus 5.5 only when a step needs deeper reasoning.
Covered in this guide
- Haiku 5.5: Anthropic's smallest and fastest 5.5 model, released October 7, 2026, with a 1M context window, built for high-volume work.
- Opus 5.5: Anthropic's September 2026 flagship LLM with a 1 million token context window, built for long-running agentic coding and computer use.
- Sonnet 5.5: Anthropic's fastest Sonnet-class model, launched in September 2026, with a 1M context and output more than 30% faster than Sonnet 5.
- Fable 5.1: Anthropic's second Mythos-class model, released Sept 1, 2026, for long-horizon agentic coding and research at Fable 5's per-token rates.
- Anthropic: Anthropic is a Public Benefit Corporation started by 7 ex-OpenAI researchers. It builds the Claude model family and counts Amazon and Google among its largest backers.
- Claude app: Claude is Anthropic's AI assistant, with a free tier, paid personal plans, and Team and Enterprise seats. Opus access starts at the first paid plan.
- Fable 5: The first generally available Mythos-class Claude model, with 1M context and 95.0% SWE-bench Verified. Released June 2026 by Anthropic.
- Mythos 5.1: Anthropic's Mythos-class model, identical to Fable 5.1 but with safeguards relaxed for verified cyber and life-sciences users, scoring 1,853 on GDPval-AA v2.
- Opus 4.8: Claude Opus 4.8 (May 2026): Anthropic's most capable model. 1M context window, 88.6% SWE-bench Verified, $5/$25 per 1M tokens. Excels at long-horizon coding and complex reasoning.
- Sonnet 5: Claude Sonnet 5, released by Anthropic on June 30, 2026, hits 82.1% SWE-bench Verified with a 1M-token context window.
- Consensus: AI-powered search engine for peer-reviewed research literature
- GPT-6 Luna: GPT-6 Luna (Sept 2026) is OpenAI's lowest-cost GPT-6 model, tuned for high-volume chat, extraction and classification with six adjustable reasoning-effort levels.
- GPT-6 Sol: OpenAI's mid-tier GPT-6 model (Sep 2026), 1.05M-token context, 68.8% on DeepSWE v1.1 coding, half GPT-5.6 Sol's price.
- Kickresume: AI resume and cover letter builder used by more than 8 million job seekers, pairing AI-assisted writing with ATS-friendly templates and a website builder.
- Sierra: Enterprise AI agent platform from Bret Taylor valued at $15.8B in 2026, used by 40% of the Fortune 50 for customer service across chat, voice, and email.
- Teal: Teal is a free AI job search platform for job seekers, built by Teal Labs, founded in 2019, combining an unlimited resume builder and application tracker.
- Windsurf: Windsurf, now Devin Desktop from Cognition, is a VS Code-based editor with local and cloud agents, free with unlimited Tab and Pro at $20 a month.
- Writesonic: Track and grow your brand's presence in ChatGPT, Gemini, and Perplexity with Writesonic's GEO platform. No free plan; paid tiers only.
Sources
Still deciding?
This guide covers a handful of options. Smart Match checks every listing in the directory against how you actually work and what you can spend, then hands you the shortlist and the reason behind each pick.
Find your toolsRelated guides
- What Happened When 7 AI Agents Got Real Bank Accounts and No SupervisionAnalysisWhat changed and who it affects
- Best AI App Builder in 2026: Pick by What You're BuildingBuyer's guideHow to pick, across a category
- Best AI Assistant Apps for Android in 2026, Now That Google Assistant Is DeadBuyer's guideHow to pick, across a category
- Best AI Chatbots in 2026: Pick by the Job, Not the LeaderboardUpdatedRechecked against current sources
- Best AI Coding Assistants in 2026: Pick the Job, Not the BrandBuyer's guideHow to pick, across a category
- Best AI Companies in 2026: Who Is Actually LeadingBuyer's guideHow to pick, across a category