The Three Jobs Hiding Inside "AI Agent Observability" in 2026
AI agent observability covers three purchases in November 2026 besides tracing: pre-launch sandboxes such as Archal, eval audits and governance such as ReasonBlocks and Openlayer, and cost tools such as Codag and Touchmark. Neither the 14-tool Arize roundup nor Confident AI's top 8 names any of them.
The short version
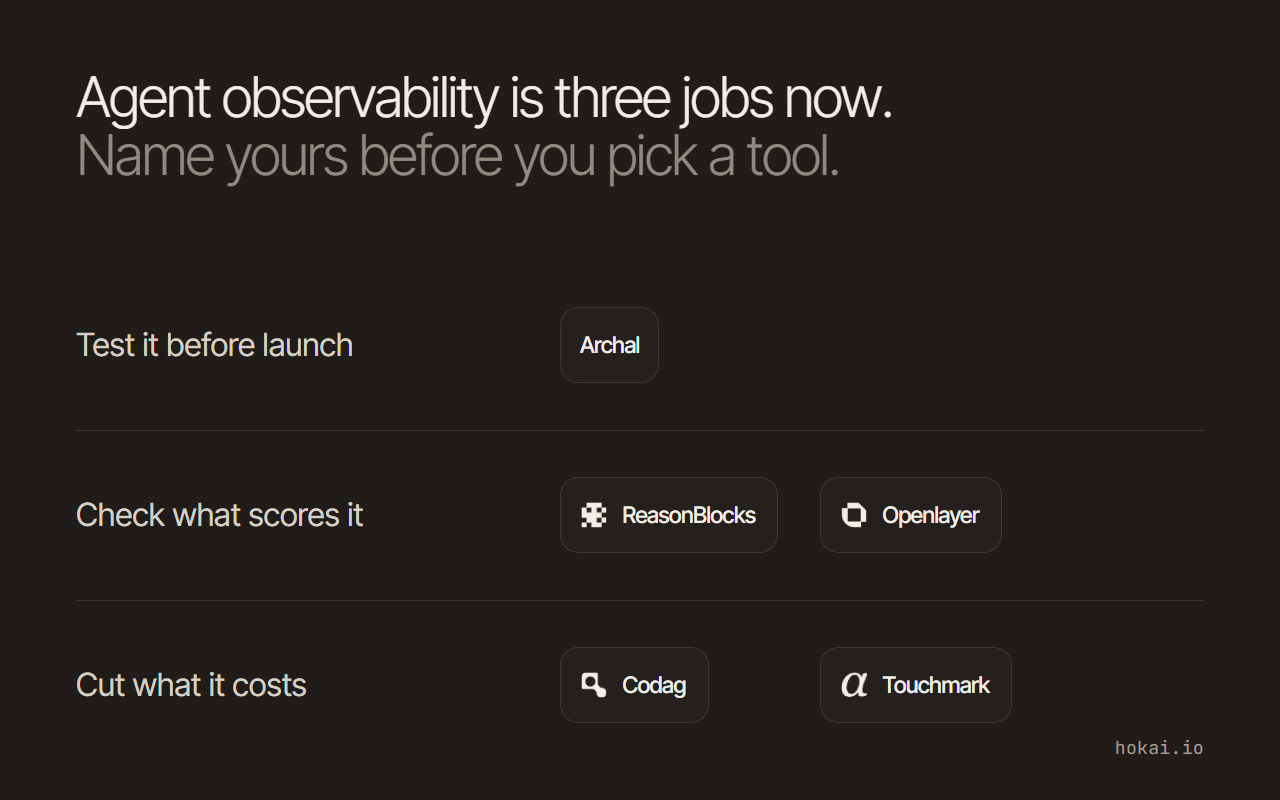
Name the job before you shop. Archal tests an agent before launch, ReasonBlocks and Openlayer check whether its evals can be trusted, and Codag and Touchmark cut what it costs to run. Three of the six tools changed what they sell since August, so read each vendor's own page the week you buy.
Not sure which one fits you? Describe your situation and Smart Match names three tools.Find my AI tools
In this guide13 sections
"AI agent observability" names three different purchases in November 2026: testing an agent before it ships, checking the evals that score it, and cutting what it costs to run. Tracing, the job most roundups mean by the word, is a fourth that LangSmith, Langfuse and Datadog already own. Of the six young tools Hokai filed under the label in August, three have changed what they sell since then, so the map this guide drew on 16 August no longer holds.
The six are Archal, ReasonBlocks, Openlayer, Codag, Touchmark and Crukx. A team that buys the wrong one usually finds out during its second incident, not its first, because the first incident is what sent them shopping, budget already approved and pointed at the wrong problem.
 The three jobs this guide sorts the tools into, from each vendor's own site, checked 9 November 2026. Hokai card.
- Tools here that changed what they sell since August
- 3 of 6
- ReasonBlocks, Touchmark, Crukx
- Tools here that still stop an agent mid-run
- 0
- The August job has no seller left
- Tools in Arize's agent observability roundup
- 14
- None of the six, updated 13 October
- When EU high-risk AI obligations start
- 2 Dec 2027
- European Commission
What Changed Since 16 August 2026
Every row below was re-read on 9 November 2026 from the vendor's own site, except ReasonBlocks, whose Hokai record was checked against its homepage and trust page on 3 November.
| Tool | August 2026 | November 2026 |
|---|---|---|
| ReasonBlocks | Runtime that caught failures mid-run | Audits and builds evals |
| Touchmark | Priced output by measured quality | Market for reserved inference |
| Crukx | Release gate for agents | Storage for model checkpoints |
| Codag | Log compression, $19 Hobby plan | Cuts coding-agent tool output |
| Archal | Sandboxes at $0.10 a minute | Same rate, one-time credit |
| Openlayer | Free Basic plan, Enterprise | Unchanged plans |
The August version split the category into tracing, mid-run intervention and outcome-based billing. Two of those jobs have no seller in this set any more: nobody here intervenes mid-run, and nobody bills by output quality. The jobs below are re-cut from what the six actually sell today.
Codag's change is quieter than those three: it still compresses logs, but its homepage now leads with test runs, search results and file trees, and its pricing moved from monthly plans to credits. Archal and Openlayer are the two whose August facts mostly still hold, which is why they anchor jobs one and two below, and why a reader who bought either in the summer has nothing to undo.
AI Agent Observability Splits Into Three Jobs, Not One
Arize's roundup of agent observability tools, updated 13 October 2026, compares 14 products, and Confident AI's "Top 8" list was updated on 23 October. Between them they cover LangSmith, Langfuse, Braintrust, Datadog, Galileo and Confident AI itself. Neither names any of the six tools in this guide, and both describe the same core job: record a trace of what the agent did, then score it.
The six do something else, and they sort into three jobs:
- Test the agent before it ships. Archal gives it stateful copies of real services to act on.
- Check what scores the agent. ReasonBlocks audits the evals and the AI judge; Openlayer runs tests and guardrails with a compliance record.
- Cut what the agent costs. Codag shrinks the tool output a coding agent reads; Touchmark sells reserved inference that it says typically clears below retail.
The sixth, Crukx, has left the category: it now stores model checkpoints, a job no agent-observability buyer is shopping for.
How to Choose: Name the Job Before the Tool
Answer four questions before comparing a single tool. They narrow the field faster than any feature table.
Is the agent live yet? Before launch, the risk is an untested edge case, and a sandbox answers it. After launch, the risk moves to whether you can trust the scores your evals produce, and to the bill.
Do you trust your own evals? If the agent passes every test and still fails in front of users, the problem is the test, not the agent. That is an eval-audit job, not a tracing one.
Is the bottleneck tokens or answers? A coding agent that burns budget reading 4,000-line test logs has a tool-output problem. An agent that is confidently wrong has an evaluation problem. Those are different products, even though both get marketed under the same word.
Can procurement sign a contract today, or do you need to start this afternoon? ReasonBlocks works through a booked call and publishes no price. Archal, Codag and Openlayer let you start free, and Touchmark lets a buyer sign up and post a request for quotes.
If you are still not sure which job yours is, answer a few questions and get a shortlist matched to your use.
The Shortlist at a Glance
Five tools remain in the category after Crukx's move. The table sorts them by job and by how you pay; the sections under it explain the catch in each.
| Tool | Job | Start without a call? | Price basis |
|---|---|---|---|
| Archal | Test before launch | Yes, one-time credit | $0.10 per sandbox minute |
| ReasonBlocks | Check the evals | No, booked call | Unpublished |
| Openlayer | Check and govern | Yes, free Basic plan | Enterprise is quoted |
| Codag | Cut tool-output cost | Yes, free credits | $0.05 per credit |
| Touchmark | Cut inference cost | Yes, post a request | Bids per contract |
Prices are the vendors' own, read on 9 November 2026. Two of the five have no figure a buyer can budget from without talking to someone: ReasonBlocks sets its price on a call, and Touchmark's depends on what providers bid for your order.
Job One: Test the Agent Before It Ships
Archal gives an agent stateful sandboxes of 22 services, among them GitHub, Slack and Stripe, so it can write to something that behaves like the real thing without touching production. It supplies the environment only: your own evaluator and CI decide whether the run passed.
There is no subscription. Each verified workspace gets a one-time $20 credit, released in two parts, with no card required, and after that every ready environment bills by the active minute, prorated by the second, according to Archal's own billing FAQ.
As of 9 November there is no self-serve paid plan to continue on once the credit is used, so a team that likes the trial has to talk to Archal to keep going. The caveat: this answers "will this break" before launch, not "what just broke" in production.
Archal is not the only way to test before launch. Kashikoi runs no-code simulations of your own agent, and E2B isolates untrusted code in microVMs rather than standing in for third-party APIs.
Job Two: Check What Scores the Agent
ReasonBlocks launched in August as a runtime that caught failures while an agent was still running. It no longer sells that. Its homepage now offers to review the eval suite a team already runs, or draft one from agent traces, and to test whether an AI judge's scores match human reviewers before launch. Its trust page describes a capture gateway that forwards traffic to OpenAI or Anthropic on the customer's own key, and candidate model training on the captured data using Tinker from Thinking Machines Lab.
It publishes no prices. Access runs through a booked conversation, and paid work draws on organisation credits bought through Stripe, with an approval step before any paid baseline, training or evaluation run. The August headline figures, a 42 percent accuracy gain on 75 SWE-Bench Pro problems, described the old runtime and no longer belong in a buying decision. Our Archal vs ReasonBlocks comparison covers the two side by side.
Openlayer frames itself as a governance platform first: an inventory of AI systems, 175-plus evaluation tests and runtime guardrails that produce audit-ready evidence. Its free Basic plan is capped at 1 member, 5 projects, 20 tests per project, 20,000 requests a month and 3-month data retention; Enterprise is custom-quoted.
Its security page, read on 9 November, says it holds SOC 2 Type II, monitored continuously with Vanta and audited by Insight Assurance, is GDPR compliant, and "supports HIPAA-aligned use cases". In August the same page said the platform was not HIPAA compliant unless self-hosted, so a team in healthcare should ask what that wording now covers before relying on it.
Job Three: Cut What the Agent Costs
Codag launched around log compression and now pitches a wider job: cutting what coding agents such as Claude Code and OpenAI Codex spend reading their own tool output. A single test run can print 4,212 lines when the agent needs one failing assertion; Codag hands the agent that failure and keeps every omitted line retrievable on your own machine.
It bills in credits. A new account gets 10 free credits, about 1 GB of log output, and log compaction spends roughly one credit per 100 MB, which works out to about $0.50 per GB on Codag's pricing page of 9 November.
Teams that run agents every day can take the Team plan at $499 a month for 12,500 credits instead. The caveat: only Claude Code and Codex are attached automatically, and inference-based context reduction spends credits about 1,000 times faster than logs, so the per-gigabyte figure depends on what you reduce.
Touchmark does not trace, score or compress anything. It is a market for reserved inference: a buyer posts a request for quotes for a monthly block, such as 1 billion tokens of Kimi K3 Fast, with the service levels it needs, and several providers bid. Touchmark's homepage says trades typically clear 10 to 60 percent below retail, buyers pay no transaction fees, and unused capacity can be resold; it also sells hourly throughput up to 3 hours ahead for peaks.
That only pays off for a team that already knows its inference volume. For a team that first needs to see where AI spend goes, SuperPenguin attributes provider costs to a customer, feature or pull request, and Maitai works on production LLM traffic itself. Our ReasonBlocks vs Touchmark comparison follows both pivots in detail.
Crukx Left the Category
Crukx called itself "the release gate for AI agents" in August. Its site now lives at crukx.dev and sells something unrelated to agents: CRX stores a fine-tuned model as a lossless delta from its parent and rebuilds it byte for byte. On its measured Qwen2.5-14B pair, a 29.5 GB model became an 8.2 GB delta. Its Model Explorer is free with no account and its CLI is a free private alpha.
Its older domain, observai.dev, still shows a third product, a model-optimization pipeline with a waitlist, so a buyer who lands there first gets the wrong picture. For a team running agents, Crukx is no longer on the shortlist; for a team storing dozens of fine-tunes of one base model, it is worth a look. Our Codag vs Crukx guide explains the split.
Archal vs ReasonBlocks: Test the Agent, or Test the Tests
These two still get confused because both are 2026 Y Combinator companies that promise fewer agent failures before launch. The difference is what they test.
Archal tests the agent. You point it at a sandboxed copy of the APIs it calls, run your scenario, and your evaluator reads the result. Reach for it when the risk is an agent writing the wrong thing to GitHub or Stripe.
ReasonBlocks tests the tests. It checks whether the evals and the AI judge that grade your agent agree with people, and builds evals from traces when you have none. Reach for it when the agent passes your suite and still disappoints users.
Pick Archal if you are pre-launch and need somewhere safe for the agent to act. Pick ReasonBlocks if you already have evals and are not sure the scores mean anything.
Openlayer's Compliance Bet Is Early, Not Bolted On
The European Commission's AI Act page, read on 9 November, says the Act became applicable on 2 August 2026, with its transparency rules taking effect that month. Obligations for high-risk systems used in areas such as employment, education and border control apply from 2 December 2027, and those for AI built into regulated products from 2 August 2028, a timeline set by the AI Omnibus amendments.
Openlayer is the one tool in this set built around that requirement rather than adding a compliance page after the fact: EU AI Act mapping sits next to its evaluation tests as a first-class feature. A startup shipping its first agent this quarter still has over a year before the earliest high-risk obligation applies, while a vendor selling into regulated buyers may already be fielding the question from procurement.
Who Should Skip the Category Entirely
If your agent runs fewer than a few dozen sessions a day and a human already reviews every output before it reaches a customer, none of these tools earn their setup cost yet. A Slack channel where failures get pasted, plus a spreadsheet tracking them, will outperform any paid tool at that volume, because the problem you have is review capacity, not blind spots.
The threshold to revisit that is roughly when nobody on the team can describe, from memory, the last three ways the agent failed. At that point spend a day on Openlayer's free Basic plan or Codag's free credits before paying for anything. The cost of finding out you were wrong is one afternoon, not a quarter of budget.
What Would Change the Verdict
This guide sorts the tools by job, not by rank, so the verdict that can move is which tool owns each job. Five things would change it, and each is something a reader can check on the vendor's own page.
ReasonBlocks publishes a price. Today the eval-audit job has no figure a buyer can plan around. A public plan would let a small team try it without a call, and would make it the default answer for job two rather than one option beside Openlayer.
Archal opens a paid self-serve plan. Its one-time credit is generous for a trial, but a team that wants to keep testing has nowhere to put a card yet. Until it does, the trial is easy and the second month is a conversation.
Codag attaches more agents. Two attached agents is a narrow base. If Cursor or another agent users run every day joins Claude Code and Codex, Codag stops being a niche choice for job three.
Touchmark's discount shows up in public data. The 10 to 60 percent range is Touchmark's own description of where trades clear. Published fills, or a buyer who reports one, would show whether a small team gets the low end or the high end.
A tracing incumbent ships one of these jobs. If LangSmith, Langfuse or Datadog adds stateful API sandboxes, eval audits against human reviewers or tool-output reduction, the case for a separate young vendor weakens for that job.
Openlayer's HIPAA wording is a sixth watch item for healthcare buyers only: if the security page spells out what "HIPAA-aligned" covers, the governance answer for that group gets simpler.
The Case for Just Using LangSmith or Datadog Instead
The strongest objection to everything above is simple: these are young companies, three of them changed products since August, and betting a production workflow on a startup that pivots every quarter is a real risk. LangSmith, Langfuse, Datadog and Arize are established, well funded, and already trusted by teams running LangChain or Datadog APM.
For the tracing job, that objection is right. If your team already pays for Datadog or works inside LangChain, start there rather than adding another vendor for the same function.
But tracing is not what these six do. A sandbox of third-party APIs, an audit of whether your judge agrees with people, a cheaper way to read tool output, and a forward contract for tokens are jobs a trace viewer is not built for. Testing whether you need one costs a free credit, not a procurement cycle. The pivots are also the best argument for reading a vendor's own homepage the week you buy, not a roundup from the summer, this one included.
Frequently asked questions
What's the difference between AI agent observability and LLM observability?
LLM observability tracks a single model call: the prompt, the response, the token count. Agent observability tracks a multi-step chain where an agent calls tools and often other models within one session, so a failure can show up three steps in with no single bad completion at the center. That is why trace tools built agent-specific views instead of reusing plain LLM-monitoring dashboards.
Do I need a paid tool for a small AI agent deployment?
Not at first. Openlayer's Basic plan is free for one member and five projects, Codag gives new accounts free credits, and Archal grants a one-time sandbox credit, so a small team can test each job before paying. Paying becomes necessary once volume outgrows those allowances or a compliance requirement forces an enterprise contract.
Which of these tools can I start using without a sales call?
As of 9 November 2026, Archal, Codag and Openlayer all let you sign up and start free, and Touchmark lets a buyer sign up and post a request for quotes. ReasonBlocks works through a booked conversation and publishes no prices, and Crukx has moved out of this category.
Does any tool still stop an agent mid-run?
Not among these six. ReasonBlocks sold a runtime that caught failures mid-run when it launched in August 2026, then moved to auditing and building evals. Teams that want live correction of production output can look at Maitai, which watches LLM traffic and fixes bad answers as they happen.
When do the EU AI Act's high-risk obligations actually take effect?
Obligations for high-risk systems used in areas such as employment, education and border control apply from 2 December 2027, and those for AI built into regulated products from 2 August 2028, per the European Commission's AI Act page. The Act itself became applicable on 2 August 2026, so the urgency in many vendor pitches runs ahead of the high-risk deadline.
Covered in this guide
- Archal: Stateful API sandboxes for testing AI agents and integrations: 22 environments such as GitHub, Slack and Stripe, billed per environment-minute. YC S26.
- Claude Code: Anthropic's agent for the terminal, IDEs, desktop, web and mobile that edits files, runs tests and opens pull requests. There is no free plan.
- Codag: Cuts AI coding-agent costs by trimming oversized tool results, from test runs to grep output, down to the lines that matter, with the rest kept on your machine.
- Confident AI: LLM evaluation and tracing platform from the DeepEval team, with a free plan, CI regression tests and SOC 2 Type II.
- Crukx: Stores related model checkpoints as exact deltas from their parent model, so fine-tunes take less space to keep and move. Free Explorer, CLI in private alpha.
- E2B: Enterprise sandbox infrastructure for AI agents to execute code securely. Firecracker microVMs, sub-second cold starts, Python and JavaScript SDKs. Free tier with $100 credit; paid plans scale up to enterprise BYOC deployment.
- Kashikoi: Kashikoi is a no-code simulation platform for evaluating AI agents, built by the ex-Moveworks lead behind 250+ shipped enterprise agents.
- Kimi K3: 2.8T-parameter open-weight MoE model from Moonshot AI (July 2026) with a 1M-token context window and the top published open-weight result on GPQA Diamond.
- Maitai: Maitai is a $50 to $200/mo control plane that indexes production LLM traffic and auto-corrects bad output in real time with Sentinels.
- OpenAI Codex: Clones a GitHub repo into a sandbox, writes and tests code, then opens a pull request; included in every ChatGPT plan, with the newest GPT-6 models from Plus.
- Openlayer: AI governance platform with an AI system inventory, 175+ evaluation tests and runtime guardrails that produce audit-ready evidence for regulators.
- ReasonBlocks: YC-backed startup that audits a team's AI evals and tests judge scores against people, with candidate model training on the side. No public pricing.
- SuperPenguin: AI spend platform with 2 native SDKs (Python, TypeScript) that attributes provider costs to a customer, feature, or pull request instead of one monthly total.
- Thinking Machines Lab: San Francisco AI lab started by ex-OpenAI CTO Mira Murati, maker of the Tinker fine-tuning API and three Inkling language models.
- Touchmark: AI inference forward market (YC S26) where buyers lock in future token capacity on models like GLM, Kimi and Qwen below list price, delivered through an OpenAI-compatible API.
Sources
Still deciding?
This guide covers a handful of options. Smart Match checks every listing in the directory against how you actually work and what you can spend, then hands you the shortlist and the reason behind each pick.
Find your tools