What Qwen Is Actually For, Now That the Weights Are Out
Qwen is Alibaba's model family. Its flagship, Qwen3.8-Max, is a 2.4 trillion parameter mixture-of-experts model with a 1 million token context window, sold through Qwen Cloud at $2 and $6 per million tokens. Open checkpoints exist: a 27 billion parameter Apache 2.0 model and the flagship under a custom licence.
The short version
Qwen3.8-Max still costs $2 input and $6 output per million tokens, 40% less on output than Claude Sonnet 5.5. The open weights shipped, but the 2.4 trillion parameter flagship needs a cluster and a custom licence. Most self-hosters should look at the Apache 2.0 27B model.
Not sure which one fits you? Describe your situation and Smart Match names three tools.Find my AI tools
In this guide10 sections
Alibaba launched Qwen3.8-Max on August 3, 2026 at $2 per million input tokens and $6 per million output tokens. Almost three months later, the price has not moved, and the promise that made the launch interesting has been kept. The weights are public. Mostly.
That changes who should care. In August the story was a cheap API with a self-hosting option "due days later". As of October 26, 2026, the option exists, and it comes with a size, a licence and a hardware bill that the launch coverage never priced in. This update re-reads the primary sources: Alibaba's own model page, the Hugging Face repositories, and the pricing pages of the rivals the first version compared against.
If you route model calls for a product, the short version is this. Qwen is still the cheapest way to get a 1 million token context window from a lab with frontier-level claims, at least among the vendors whose pricing pages I could read this week, but it is no longer the only cheap option, and the "free upgrade" framing from August has aged badly. Plan accordingly.
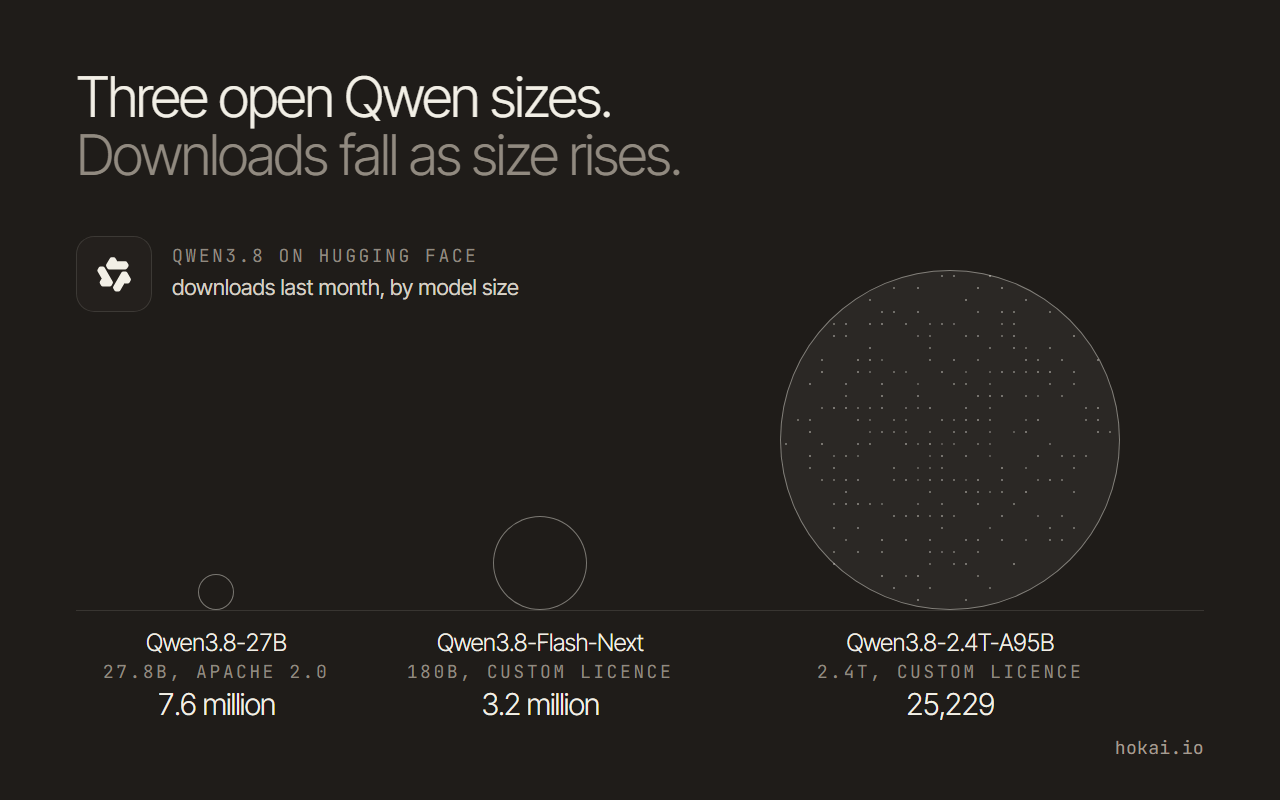 Hokai chart of Qwen's three open-weight repositories by size and last month's downloads, from Hugging Face as captured on 26 October 2026.
What changed since August
I wrote the first version of this guide the week of the launch, working from launch coverage and a handful of vendor pages. Five things in it are now out of date, and one of them was simply my error.
The weights shipped. Qwen3.8-27B appeared on Hugging Face in early August under Apache 2.0. The flagship checkpoint followed under a custom licence. The first version said neither had landed.
The Claude "promotion" never ended. I wrote that Claude Sonnet 5 would climb to a higher rate on August 31. It did not. Anthropic's page still lists it at the introductory rate, and Claude Sonnet 5.5 lists at the same rate.
OpenAI's flagship got cheaper. GPT-5.6 Sol now lists at $4 and $20, and OpenAI marks the price promotional.
DeepSeek's budget model was retired. I named V4 Flash as the cheap rival. DeepSeek retired it, and V4.1 Flash now lists at $0.15 input and $0.60 output off-peak.
A new Anthropic tier exists. Claude Opus 5.5 is cheaper than Claude Opus 5, at the prices in the table below.
Taken together, those five changes matter for how you read the rest. Where I can now read a vendor page directly, I have, and where I could not, I say so. None of this makes the August advice wrong. The comparison is just tighter than the headline suggested. Cheap is no longer rare.
The price table, October 2026
All prices are per million tokens, taken from the vendors' pricing pages on October 26, 2026. Qwen's come from the Qwen Cloud model page.
| Model | Input | Output |
|---|---|---|
| Qwen3.8-Max | $2.00 | $6.00 |
| Claude Sonnet 5.5 | $2.00 | $10.00 |
| Claude Opus 5.5 | $4.00 | $20.00 |
| Claude Opus 5 | $5.00 | $25.00 |
| GPT-5.6 Sol (promotional) | $4.00 | $20.00 |
| DeepSeek V4.1 Flash (off-peak) | $0.15 | $0.60 |
Read the table by output, because that is where agent workloads spend. Qwen3.8-Max costs 40% less on output than Sonnet 5.5 and 70% less than Sol. On input it only ties Sonnet.
Alibaba also lists cached input at $0.25 per million tokens, a 1 million token context window and up to 131,072 tokens of output. The context price is flat, with no step-up past a threshold. For long-document work, that matters more than the headline rate.
Two caveats. Short ones. First, DeepSeek's page says off-peak rates are half the peak rates, and peak hours run on weekday mornings UTC. Second, the benchmark scores that justify the Qwen premium over DeepSeek are covered below. Price alone does not pick a model.
For a wider view of who is cheapest this month, see the cheapest LLM API guide and the model leaderboard, which show the numbers as they stand rather than as they stood in August.
Who this affects first
Teams that already buy tokens through a router get the simplest win. OpenRouter lists the hosted Qwen3.8 family, so trying the model means changing one string. No contract, no new billing relationship.
Hosts that serve open checkpoints have a new product. Together AI and Fireworks AI can serve the weights at their own margin, provided the licence terms allow it. That proviso is the whole story in the next section.
Small teams with a coding agent in production have a concrete test to run, and the test is cheap enough that skipping it is hard to defend. Take one real task, run it on Sonnet 5.5 and on Qwen3.8-Max, and compare cost per accepted result instead of cost per token. Output is where the 40% saving lives. Agent loops produce a lot of it.
Developers who want to run something locally have a better answer than the flagship. The 27B model is the one that fits on hardware a normal team can buy, and more on that below.
What "open weights" actually means here
The August version of this guide treated open weights as one thing. There are now three Qwen3.8 releases on Hugging Face worth separating, and they are very different products.
| Release | Size | Licence | Downloads, last month |
|---|---|---|---|
| Qwen3.8-27B | 27.8B parameters | Apache 2.0 | 7.6 million |
| Qwen3.8-Flash-Next | 180B parameters | Custom licence | 3.2 million |
| Qwen3.8-2.4T-A95B | 2.4T parameters | Custom licence | 25,229 |
The download counts come from the Hugging Face API on October 26, 2026. They tell you where real use is. The 27B model has roughly 300 times the downloads of the flagship. Few teams can run the flagship at all, since it needs a cluster of the kind most companies rent by the hour instead of owning, and that gap is the real story of the open release.
The arithmetic is blunt. The repository's tensor type is BF16, which is two bytes per parameter, so the checkpoint is close to 4.9 terabytes. An FP8 build exists and halves that to about 2.4 terabytes. Both figures are my arithmetic from the parameter count, not a number Alibaba publishes. Either way, this is multi-node cluster territory. Only 95 billion parameters are active per token, which helps speed, but every expert still has to sit in memory.
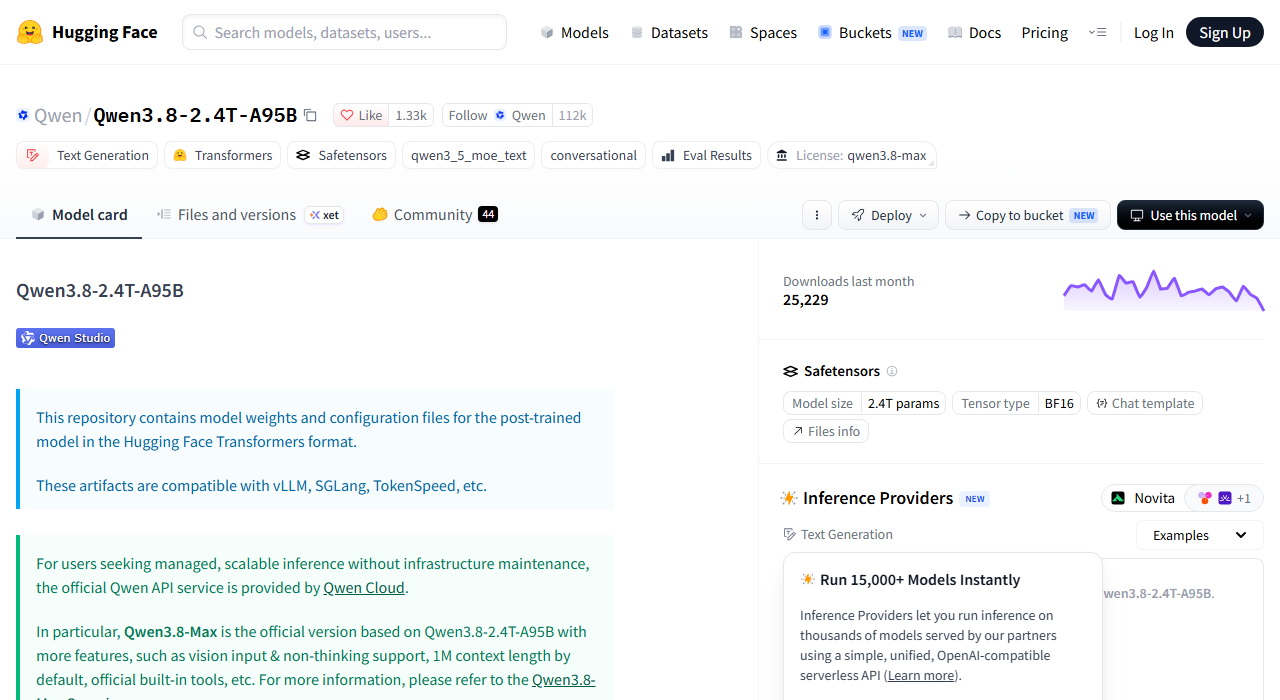 The flagship repository on Hugging Face, captured 26 October 2026.
The flagship licence is not Apache
Alibaba's own licence file for the 2.4T model is short and mostly permissive. You may use, modify, host and sell it. Two conditions apply:
- A commercial product with more than 100 million monthly users, or more than $20 million in monthly revenue, must show the model name prominently in its interface.
- A company that runs a "Model as a Service" or "AI Work Assistant" business, and whose combined revenue passes $50 million in any twelve months, needs a separate licence from Qwen before commercial use. Internal use that does not expose the model to third parties is excluded.
The second clause is the one to read twice. It is aimed at exactly the companies most likely to host the weights for others: inference clouds and coding-assistant vendors above that revenue line. A startup under it is free to build. A large host is not, without a deal. This is a summary, not legal advice. The full text takes five minutes to read.
The 27B model carries no such clause. It is plain Apache 2.0, with no revenue test and no naming requirement. For most self-hosters, that is the practical open release.
If local hardware is the goal, Ollama and the Hugging Face hub are the usual route, and our guide to the best AI models for local coding covers what fits on a single machine. To choose the app that runs it, see Ollama vs LM Studio.
Who this hurts
DeepSeek is squeezed from two directions. Its old cheap Flash model is retired, and V4.1 Flash is cheaper than Qwen by an order of magnitude on output. The pitch has shifted from "good enough and cheap" to "far cheaper, and you decide whether good enough is enough". For simple, high-volume work, DeepSeek still wins on cost. The retired DeepSeek V4 Flash stays in the catalog as a record.
Anthropic has not raised Sonnet, and Opus 5.5 undercuts Opus 5. Its lever against cheap rivals is capability per dollar at the top. For small jobs it also sells Haiku 5.5, which lists at $0.10 input for prompts up to 100,000 tokens. If you are choosing between its models, our Claude model guide lays out the trade.
OpenAI lists Sol at $4 and $20 as promotional pricing. A promotion with an end date is a risk for anyone budgeting a year ahead. Its lower tiers, GPT-5.6 Terra and GPT-5.6 Luna, sit under Sol and are worth pricing on your own workload.
Other Chinese-lab models belong on the same test. Kimi K3 and GLM 5.3 are both in the catalog, and a fair shortlist prices them on your task too.
The benchmark question has partly resolved
In August, every score for Qwen3.8-Max came from Alibaba. That is still mostly true, but the picture has two more pieces.
The first is the model card. Alibaba's own table on the Hugging Face page shows Qwen3.8-Max at 86.6 on Terminal-Bench 2.1, against 88.8 for GPT-5.6 Sol at its highest setting and 84.6 for Claude Opus 4.8 and Claude Fable 5. The previous Qwen flagship, Qwen3.7-Max, scored 74.5 on the same test. That is a 12-point jump in one generation, and it is vendor-run.
The second is an independent number. Artificial Analysis lists an Intelligence Index of 40 for Qwen3.8-Max, a blended price of $1.18 per million tokens and about 41 output tokens per second. Our model record holds those figures, last checked on September 14, 2026.
An index of 40 is respectable. It is not a frontier score, and nobody should pretend it is. Speed is slow for interactive use. Take it as the honest version of the launch claim: strong on agentic coding by its own test, middling on a third-party composite, and not fast.
None of this contradicts the price story. It sets the expectation. You are buying a cheaper model that is close to the leaders on some tasks, not a drop-in replacement for them on all tasks. Our Fable 5.1 record shows where the top of the market sits, if you want the contrast.
The case against switching
The strongest argument for staying put is not about price. It is about what a cheaper model costs you in the other column.
A cheaper token is not a cheaper answer. Suppose Qwen needed a retry on 15% of tasks that Sonnet 5.5 finishes first time; a good part of the output saving would go on those retries. No public benchmark measures that for your workload. Only a test on your own tasks does.
Data residency is the second cost. The hosted API runs on Alibaba Cloud, and the Qwen Cloud page I read was set to its Singapore region. Teams with contractual limits on where data is processed, or on which parent company can touch it, may rule this out regardless of price. The open weights are the way around it, but only the 27B model is realistic to host.
The third cost is operational, and it is the one that surprises people after the pilot works. A flat 1 million token context is an asset on paper. In practice, long contexts drive latency and cost on any provider, and a 41 tokens per second output speed makes long agent loops feel slow.
My answer to all three is the same. Run a small, real comparison before you move anything. Qwen3.8-Max is worth that test, because a 40% cut on the line item that dominates an agent bill is real money at any volume above hobby scale. It is not worth a migration on the strength of a price table, and it is certainly not worth one on the strength of a launch-week headline.
What to do this week
- Pick one workload where output tokens dominate, such as a coding agent.
- Run it on your current model and on Qwen3.8-Max, same prompts, same scoring.
- Compare cost per accepted result, not cost per token.
- If self-hosting matters, test the 27B model first.
- Skip the 2.4T checkpoint unless you already run a GPU cluster.
Stuck on the shortlist? Smart Match takes a few answers about budget and use case and returns matched options. The model recommender works from constraints such as price and context size.
For a broader decision framework, see how to choose the right LLM.
What to watch
Three things will decide whether this update ages better than the first. Watch them.
- The licence in practice. Whether inference hosts sign deals under the Model-as-a-Service clause, or avoid the flagship, shows how open the release really is.
- The Sol promotion. OpenAI's lower price runs at least through November 21, 2026. If it ends, the gap with Qwen widens again.
- Independent evaluations. The Artificial Analysis figures here are six weeks old. A fresh run, or a third-party agentic benchmark, would settle the argument the model card cannot.
The August guide ended on a licence that had not yet landed. This one ends on a licence that has, and the lesson holds: read the terms before building on the price. Then run your own test.
Frequently asked questions
What is Qwen3.8-Max actually for?
It is Alibaba's flagship model for coding, agent workflows and long documents, with text, image and video input and a 1 million token context window. It lists at $2 input and $6 output per million tokens on Qwen Cloud. Its strongest published result is on agentic coding, and that figure comes from Alibaba's own model card.
How does Qwen3.8-Max pricing compare to Claude and GPT-5.6?
As of October 26, 2026 it ties Claude Sonnet 5.5 on input at $2 and costs 40% less on output ($6 against $10). GPT-5.6 Sol lists at $4 and $20 under a promotion that runs at least through November 21, 2026. DeepSeek V4.1 Flash is far cheaper at $0.15 and $0.60 off-peak.
Are Qwen3.8 open weights available?
Yes. Qwen3.8-27B is on Hugging Face under Apache 2.0, and the 2.4 trillion parameter Qwen3.8-2.4T-A95B checkpoint is there under a custom licence. The flagship file set is about 4.9 terabytes in BF16, so it needs a multi-node GPU cluster to run.
What licence does the Qwen3.8 flagship use?
A custom licence that permits commercial use, modification and hosting. Products above 100 million monthly users or $20 million monthly revenue must display the model name. Model-as-a-Service and AI work assistant businesses above $50 million in twelve-month revenue need a separate licence from Qwen. Read the full text before building a hosted product.
Should I switch from Claude or GPT to Qwen3.8-Max to save money?
Test it first. Output tokens are where the saving lives, but cost per accepted result matters more than cost per token. Run one real workload on both models, compare retries and quality, and check your data residency rules. An independent Artificial Analysis index of 40 suggests strong, not leading, general performance.
Covered in this guide
- Qwen: Alibaba's free Qwen chat app for web, desktop and mobile, plus a per-token Model Studio API and open-weight models you can self-host.
- Qwen3.8-Max: Qwen3.8-Max is Alibaba's flagship MoE model, launched Aug 2026, with a 1M-token context, native multimodal input, and a text-only open-weight checkpoint released weeks later.
- Qwen Cloud: Alibaba Cloud, founded 2009, is China's top cloud provider (35% share) and builds the Qwen AI models, which passed 1 billion Hugging Face downloads in 2026.
- Anthropic: Anthropic is a Public Benefit Corporation started by 7 ex-OpenAI researchers. It builds the Claude model family and counts Amazon and Google among its largest backers.
- Claude Fable 5: The first generally available Mythos-class Claude model, with 1M context and 95.0% SWE-bench Verified. Released June 2026 by Anthropic.
- Fable 5.1: Anthropic's second Mythos-class model, released Sept 1, 2026, for long-horizon agentic coding and research at Fable 5's per-token rates.
- Haiku 5.5: Anthropic's smallest and fastest 5.5 model, released October 7, 2026, with a 1M context window, built for high-volume work.
- Claude Opus 5: Anthropic's July 2026 Opus with a 1M token context and xhigh reasoning effort, still active but superseded by Claude Opus 5.5 on September 22, 2026.
- Claude Opus 5.5: Anthropic's September 2026 flagship LLM with a 1 million token context window, built for long-running agentic coding and computer use.
- Claude Sonnet 5: Claude Sonnet 5, released by Anthropic on June 30, 2026, hits 82.1% SWE-bench Verified with a 1M-token context window.
- Claude Sonnet 5.5: Anthropic's fastest Sonnet-class model, launched in September 2026, with a 1M context and output more than 30% faster than Sonnet 5.
- DeepSeek V4 Flash: Retired by DeepSeek on 10 September 2026; replaced by V4.1 Flash. Legacy API name now routes to the new model. MIT weights remain on Hugging Face.
- V4.1 Flash: DeepSeek's October 2026 update to V4.1-Flash: MIT-licensed weights, image input and a 1M-token context, tuned for coding agents and long task loops.
- Fireworks AI: Enterprise inference platform for open models: serverless tokens from $0.10 per 1M, managed fine-tuning per training token, and dedicated NVIDIA GPUs from $8.00/hr. $1 free credits, self-serve, no cold starts.
- GLM 5.3: GLM-5.3 is Z.ai's text-only flagship for agentic coding and security work, with a 1M-token context, a live API and open weights.
- GPT-5.6 Luna: GPT-5.6 Luna by OpenAI (July 2026): budget-tier pricing, fastest in family, high-volume workloads. 200K context, vision plus text, capped reasoning.
- GPT-5.6 Terra: GPT-5.6 Terra is OpenAI's balanced July 2026 model, taking images and up to 1,050,000 tokens of context, now followed by GPT-6.1 Terra.
- Hugging Face: The AI community building the future. Platform for discovering, sharing and collaborating on machine learning models, datasets and applications.
- Kimi K3: 2.8T-parameter open-weight MoE model from Moonshot AI (July 2026) with a 1M-token context window and the top published open-weight result on GPQA Diamond.
- Ollama: MIT-licensed runtime that runs open-weight LLMs on macOS, Windows and Linux with a local API, plus an optional paid cloud for larger models.
- OpenAI: OpenAI builds ChatGPT, the GPT-6 family (Astra, Sol, Terra, Luna), Codex and the OpenAI API. It reports 1.2B weekly ChatGPT users and raised new funding in March 2026.
- Qwen3.7-Max: Qwen3.7-Max is Alibaba Cloud's text-only flagship agent model from May 2026, called through Model Studio's OpenAI-compatible API with a million-token context window.
- Qwen3.8-27B: A dense 27B vision-language model from Alibaba's Qwen team, open-weight since 2026 with native text, image, and video understanding.
Sources
Still deciding?
This guide covers a handful of options. Smart Match checks every listing in the directory against how you actually work and what you can spend, then hands you the shortlist and the reason behind each pick.
Find your tools