The AI Tool Ecosystem in 2026: Buy the Meter, Not the Category
AI infrastructure is sold on four billing units in 2026: tokens, machine seconds, vendor-defined credits, and user seats. Tokens and seconds fall to zero during quiet weeks. Credits and seats do not. Base fees of $150 to $400 a month sit underneath several usage plans.
The short version
Pick the meter before the vendor. For bursty work choose per-second compute that stops when your container does, which favours Modal over Replicate on identical hardware. Reserve per-hour capacity only when a machine is never idle, and treat monthly floors as the real comparison.
Want this decided for your own case? Find your tools with Smart Match, starting from this guide's question.
An Nvidia H100 costs $3.95 an hour on Modal and $5.49 an hour on Together AI, and that gap is the least useful number in this guide.
Modal quotes the same card at $0.001097 per second and charges only while a container is awake. Together AI quotes $5.49 per GPU-hour for a dedicated endpoint, which is a reservation rather than a stopwatch. Two meters, one piece of silicon, and they respond to completely different things about your workload.
We published a map of this category in May 2026. It named thirty-six tools and printed not a single price, which made it useless for the only question a buyer has. This is the replacement: five tests you can run against any vendor at this layer, then the vendors themselves, priced as read on 26 October 2026.
What changed since 6 August
Re-checked 26 October 2026, each figure against the vendor's own page. Most of the arithmetic held. Four things did not.
- Tabnine's pricing page is gone. The tabnine.com domain now forwards to Tricentis, which announced on 30 July 2026 that it had acquired Tabnine.
- Tabnine seat prices are unconfirmed. We could not read a current price, so the figures below are dated 6 August.
- OpenRouter changed its bring-your-own-key terms. The free allowance used to be counted in requests. OpenRouter's FAQ now says pay-as-you-go includes $25,000 a month of list-price usage with no fee.
- LangSmith published its conversion rate. In August the Storage Unit had no stated link to a trace. The pricing page now shows 0.005 units per additional trace, at $1.00 a unit.
- Together AI's cheapest DeepSeek row moved. DeepSeek V4 Flash is retired at the vendor, and Together lists V4.1 Flash at $0.30 per million input tokens instead of the $0.14 we printed before. Readers comparing per-token vendors should rerun their arithmetic.
Modal, Replicate, E2B, Chatbase and Exa read the same as in August.
How to choose: five questions before you compare vendors
Price lists do not rank vendors at this layer, because the same sticker number means different things under different meters. These are the criteria we apply, in the order they save money:
- Can you forecast the bill from a number you already log?
- Does the meter stop when your work stops?
- What monthly floor sits under the usage rate?
- Who defines the unit, and can they change it quietly?
- What does leaving cost on the day you sign?
The five tests below take those questions one at a time, with the vendors we priced.
Four meters cover almost everything sold at this layer
Ignore the category labels for a moment. Infrastructure for AI work bills in one of four ways, and the four behave very differently when your usage moves.
| Meter | Examples | Stops when idle? |
|---|---|---|
| Per token | OpenRouter, Together AI serverless | Yes |
| Per second | Modal, Replicate, E2B | Mostly |
| Vendor unit | Chatbase, Exa, LangSmith | Depends |
| Per seat | Tabnine | No |
Per token. OpenRouter resells other providers' models and states in its FAQ that it passes through provider pricing with no markup. It earns on credit purchases instead.
- OpenRouter charges 5.5% on card top-ups and 5% in crypto.
- Together AI's serverless rates start at $0.30 per million input tokens on DeepSeek V4.1 Flash.
- The top of its range is $3.00 in and $15.00 out on Kimi K3.
- Modal now sells tokens too, billed from the first request and outside the $30 of included compute, since 1 September 2026.
Per second of machine time. Modal, Replicate and E2B sell wall-clock seconds. The unit is small enough to look harmless. E2B's default two-vCPU sandbox is $0.000028 a second, roughly ten cents an hour before memory.
Per unit the vendor invents. Chatbase sells message credits, Exa sells search requests, and LangSmith bills in LangChain Standard Units at $1.00 each.
Per seat. Tabnine was $39 per user per month for its code assistant tier and $59 for the agentic one, both quoted on annual terms when we read the page on 6 August. Headcount is the meter. Usage is not.
Test one: can you predict next month from a number you already track?
A meter is only usable if you can already count the thing it counts.
Tokens you can count, because you send them. Requests you can count. Seats you can count without opening a dashboard at all. Seconds of container time are where teams lose the plot, because the number they track is requests per day and the number they get billed for is how long a machine stayed awake between those requests.
Run the test on a real month. If you cannot multiply one figure from your own logs by a published rate and land within about twenty percent of the invoice, you are buying on a meter you do not yet understand.
That is not a reason to walk away. It is a reason to stay on the free tier until the arithmetic works, and every vendor here has one:
- Modal gives Starter accounts $30 a month in credits.
- Exa gives free accounts $10 a month plus a $10 onboarding bonus.
- E2B hands over a one-time $100.
Test two: does the meter stop when you stop?
This is the expensive one, and the answer is in the documentation rather than on the pricing page.
Replicate's pricing page is unusually direct about it. For most private models, it says, you pay for all the time instances are online: setup time, idle time waiting for requests, and active time processing them. Public models bill only for the time a request takes. Fine-tunes with fast booting are billed only while active.
Read that again with a prototype in mind. A private model left running through a quiet Tuesday bills every second of that Tuesday. On an H100 at $0.001525 a second, a day of doing nothing is $131.
Modal's meter behaves differently: it prices CPU at $0.0000131 per physical core-second with a floor of 0.125 cores per container, and memory at $0.00000222 per GiB-second, all of it tied to a container being up rather than to a reservation. Replicate does not publish a minimum billing increment on its pricing page, so the smallest chargeable slice there is not something we can state.
Test three: find the base fee sitting under the meter
Usage pricing is often two prices wearing one coat. There is the meter, and underneath it a monthly floor that bills in a month when you ship nothing at all.
| Plan | Monthly fee | What the fee buys |
|---|---|---|
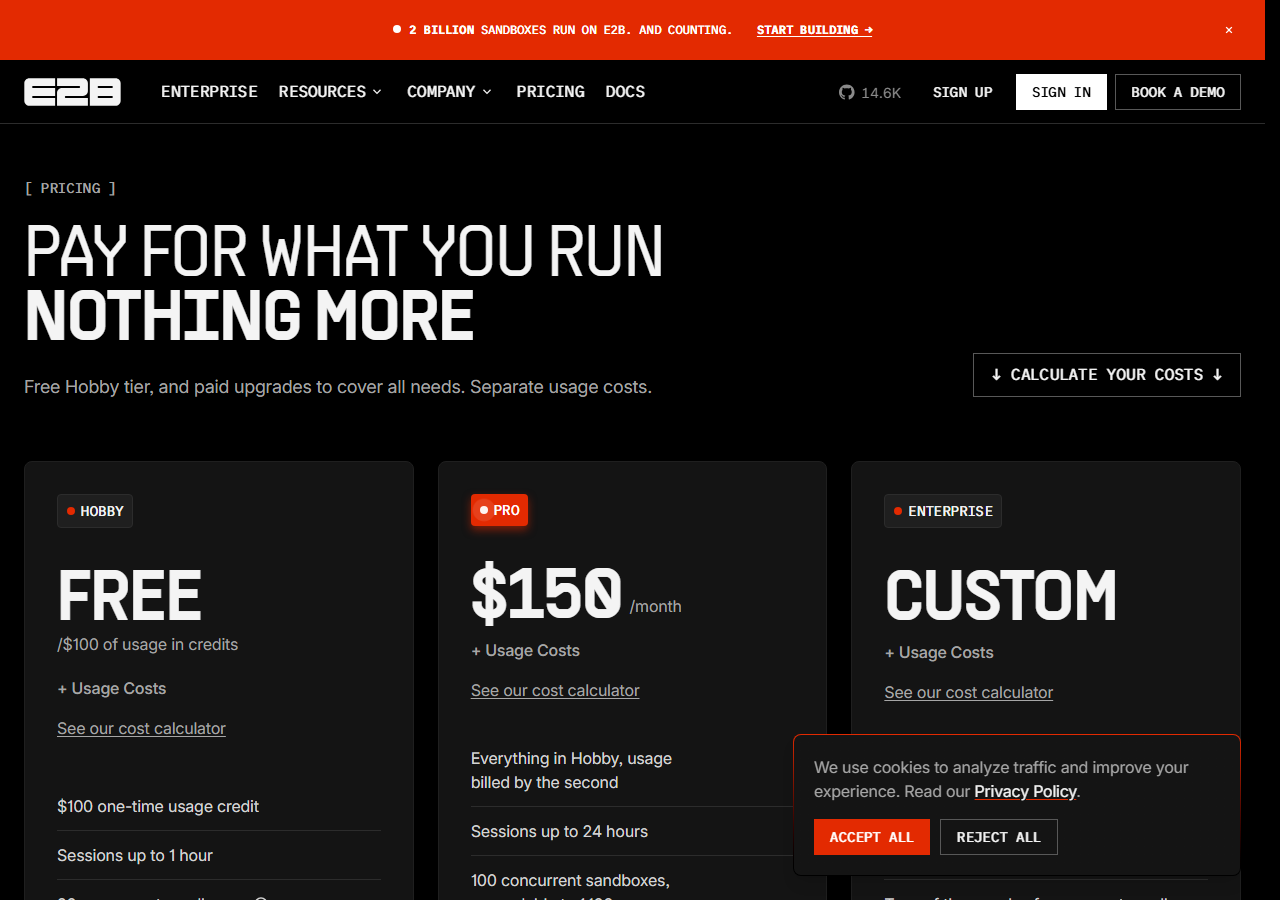
| E2B Pro | $150 | 24-hour sessions, 100 sandboxes |
| Modal Team | $250 | $100 of credits back |
| Chatbase Business | $400 | 15,000 message credits |
| LangSmith Plus | $39 a seat | 10,000 base traces |
E2B's Pro plan charges before a single sandbox second, and what the money buys is limits rather than compute: sessions of 24 hours instead of one, 100 concurrent sandboxes instead of 20, and 20 GiB of storage instead of 10.
Three more details change the arithmetic:
- E2B's concurrency ceiling can be raised to 600 for another $500 a month, or to 1,100 for $1,000.
- Modal's Team plan returns $100 of its $250 as credits, so the true floor is $150.
- Chatbase Business is $400 a month on annual billing, or $500 month to month.
Those floors are the numbers to compare, not the per-second rates. A team that runs sandboxes two hours a week is paying $150 a month for a session-length limit it will never reach.
The one-hour cap on E2B's free tier is the honest version of this. It is not a crippled product. It is a statement about which workloads the vendor wants on the paid plan, and long-running agent sessions are the answer.
Test four: who gets to define the unit?
Tokens and seconds are units the world agrees on. Credits are not.
Chatbase sells 4,000 message credits on its Basic plan billed yearly, which works out at three cents a credit. Extra credits cost four cents. Same product, same month, a third more for the marginal message.
| Chatbase item | Price |
|---|---|
| Basic plan, 4,000 credits | $120 a month |
| Extra credits | $40 per 1,000 |
| Extra agent | $300 a year |
| Remove branding | $1,188 a year |
The last two are priced independently of how much anyone uses the product.
LangSmith is the cleaner illustration, because its definition of a unit changed under us. Usage beyond the included traces is metered in LangChain Standard Units.
| LangSmith item | Figure |
|---|---|
| Developer seat | $0, 5,000 base traces |
| Plus seat | $39, 10,000 base traces |
| One unit | $1.00 |
| Extra trace | 0.005 units |
The pricing calculator now states 0.005 units per additional trace, which makes an extra trace half a cent. That is progress, and it still carries a catch. The unit also pays for other work, such as the Engine feature, where LangChain's own FAQ estimates a single run consumes roughly 7 to 45 units. One unit, two very different bills.
A vendor-defined unit is not dishonest. It is simply repriceable, and a repricing does not look like a price rise on any page a buyer bookmarks.
Test five: price the exit before you sign
Ask what a migration costs on the day you sign, while you still have a choice.
Per-token vendors are the easiest to leave, which is why OpenRouter's own answer is worth reading. Bring your own provider key and the first $25,000 a month of list-price usage carries no fee on pay-as-you-go. Beyond that the fee is 5% of what the same model and provider would cost through OpenRouter. The exit is priced, published, and small, and the allowance is now measured in dollars rather than requests.
Tabnine is the cautionary case for this test. Its enterprise plan offered an option to point the product at a model you host, with the seat fee covering the tool rather than the inference. Since the Tricentis deal, the vendor's own domain no longer carries a price list, so a buyer who signed on the August terms has no public page to hold the vendor to. Ask for the price in writing.
Per-second compute sits in the middle. Container images and a Python decorator are portable in a way a proprietary credit balance is not.
Modal against Replicate is the head to head most teams actually face
Both sell GPU seconds. Both have a free entry point. They are close enough that most teams shortlist exactly these two and then choose on brand recognition, which is the wrong tiebreaker.
| GPU | Modal per second | Replicate per second |
|---|---|---|
| H100 | $0.001097 | $0.001525 |
| A100 80GB | $0.000694 | $0.001400 |
| T4 | $0.000164 | $0.000225 |
On a single H100 Replicate is 39% more for the same card. Across the rest of the fleet the gap holds. Replicate's rate card is simpler, with prices quoted for one, two, four and eight card configurations, topping out at $0.012200 a second for eight H100s.
The verdict for a team of two to fifteen with bursty traffic: Modal's Starter plan, because the meter stops. Replicate earns the pick when you are running a public model or a fast-booting fine-tune, where its own pricing page says you are billed only for active processing, and when you want a model reachable by URL without writing deployment code.
Neither is the right answer for steady, predictable load. That is what Together AI's dedicated endpoints and on-demand clusters are for, at $5.49 and $3.99 per H100-hour.
Per-hour reservations beat per-second billing the moment your machine is never idle. A monthly rental such as Hetzner's dedicated servers is the far end of that logic. If you want a third and fourth name for the same job, the Fireworks AI and Groq records cover inference-only hosting, and the Vertex AI service is the hyperscaler option. SambaNova is a different bet again: it builds its own inference chips instead of reselling Nvidia capacity.
Who should skip this layer completely
If you are calling a hosted model through an API and storing results in a database you already run, you do not need anything in the infrastructure and platform category yet. Buy the model access, skip the rest.
The trigger for coming back is specific: you need to run code you did not write, or run a model that nobody hosts for you. Executing agent-generated code on your own server is the failure mode that sandboxes exist to prevent, and that is a security decision rather than a cost one.
Teams shopping the code and development tools shelf have a simpler version of the same question. Seat pricing there is the norm, and five agentic seats at the August Tabnine price come to $3,540 a year whether the team ships every day or takes August off. GitHub Copilot and Cursor sell on the same seat meter, so the test applies to them as well.
The strongest case against choosing by meter
The obvious rebuttal is that all of this is rounding error. A five-person team spending $200 a month across these vendors could pick the worst option on every test and lose less than one day of an engineer's salary, and the vendor that goes out of business or ships a breaking API change will cost them far more than the meter ever will.
The Tabnine episode supports that reading. A seat price that looked stable in August lost its public page in the weeks after an acquisition, and no meter test would have predicted it. Vendor continuity belongs on the checklist next to cost.
That is largely right, and it is why the tests are ordered the way they are. Test one and test two cost nothing to run and protect you from the surprise invoice. The rest start earning at the moment a base fee appears. Those fees arrive in a month when you shipped nothing, and every month after that too.
Below a few hundred dollars a month, buy on whichever developer experience your team will actually use, and revisit the choice when the invoice, not the demo, starts to drive it. Above it, the meter is the decision. If you are still unsure which tools fit your own workload, Smart Match can narrow the list from a short description of what you are building.
Data handling, security and compliance
Cost is only one column. We read what each vendor says about data, and only the claims below were confirmed on 26 October 2026.
- LangSmith: its FAQ says it does not use your traces, prompts or outputs to train models.
- OpenRouter: requests to its EU endpoint are decrypted in the EU and routed only to European provider endpoints, and its FAQ says account and billing data may still be processed in the US.
- E2B: its pricing page footer lists SOC 2 and HIPAA.
We did not confirm retention or training terms for the other vendors, so check each trust page before you send customer data through any of them.
What to watch next
The credit is the unit worth watching. Chatbase, Exa and LangSmith each bill in something they define themselves, and a vendor can change what a credit buys without any published number moving, which makes the bookmark on the pricing page a weaker safeguard than it looks.
LangSmith has now done the thing we asked for in August and published its conversion rate. The test is whether it holds. Orchestration frameworks and agent observability are the next layer up, covered in our orchestration roundup, the agent observability comparison and the wider agent list, alongside the CrewAI record.
Sources and capture dates
Every price above was read from the vendor's own page on 26 October 2026: Modal, Replicate, E2B, Together AI, OpenRouter, Chatbase, LangSmith, Exa. The Tabnine seat prices are from 6 August 2026, and the acquisition detail is from IT Brief's report of the Tricentis announcement dated 30 July 2026.
Frequently asked questions
How much does an Nvidia H100 cost per hour in 2026?
Modal lists an H100 at $0.001097 per second, which works out at $3.95 an hour, and Replicate lists the same card at $0.001525 per second, or $5.49 an hour. Together AI sells a dedicated HGX H100 endpoint at $5.49 per GPU-hour and an on-demand cluster at $3.99. The per-second vendors only bill while a container is up, so the hourly figures are not directly comparable to a reservation.
Does Replicate charge for idle time?
For most private models, yes. Replicate's pricing page says you pay for all the time instances are online, including setup time and idle time waiting for requests. Public models bill only for the time a request takes, and fine-tunes with fast booting are billed only while actively processing.
What does it cost to run untrusted AI-generated code safely?
E2B's default two-vCPU sandbox is $0.000028 per second plus $0.0000045 per GiB-second of memory, and its free Hobby tier includes a one-time $100 of credit with sessions capped at one hour. The Pro plan is $150 a month and raises that cap to 24 hours with 100 concurrent sandboxes. Modal is the alternative if you want the same isolation inside a general compute platform rather than a dedicated sandbox product.
Is per-seat pricing ever the right choice for AI tools?
It is the right choice when usage is steady and headcount is stable, because the bill is predictable and nobody has to police consumption. When we read Tabnine's page on 6 August it charged $39 per user per month for code assistance and $59 for the agentic tier on annual terms. The drawback is that a seat bill does not fall in a quiet month, so five agentic seats at that price cost $3,540 a year regardless of output.
What does OpenRouter charge on top of model provider prices?
OpenRouter's FAQ says it passes through provider pricing with no markup, so token rates match the underlying provider. It earns on credit purchases instead, charging 5.5% with a $0.80 minimum on card payments and 5% on cryptocurrency. Bringing your own provider key carries no fee up to $25,000 a month of list-price usage on pay-as-you-go, after which the fee is 5% of the equivalent OpenRouter cost.
Covered in this guide
- Modal: AI infrastructure that developers love: serverless compute for ML inference, training, and batch processing
- Chatbase: AI chatbot platform for customer support. Train on docs, PDFs, website, or Notion. Deploy to web, Slack, WhatsApp, Instagram. Free tier. $40/mo Hobby plan.
- CrewAI: Open-source Python framework for multi-agent AI, MIT-licensed with about 59.6K GitHub stars, plus the CrewAI AMP platform for building and governing agents.
- Cursor: Cursor is an AI code editor built on VS Code, widely adopted across large enterprise engineering teams, with Agent Mode, Tab completion, and Cloud Agents.
- DeepSeek V4 Flash: DeepSeek-V4-Flash-0731 is a retired DeepSeek MoE model with a 1M-token context; its old API name now routes to the successor model.
- E2B: Enterprise sandbox infrastructure for AI agents to execute code securely. Firecracker microVMs, sub-second cold starts, Python and JavaScript SDKs. Free tier with $100 credit; paid plans scale up to enterprise BYOC deployment.
- Exa: Search API that ranks the web by meaning for AI agents and retrieval pipelines, with six search types, an asynchronous research Agent and an official MCP server. A free Starter plan with monthly credits needs no payment method.
- Fireworks AI: Enterprise inference platform for open models: serverless tokens from $0.10 per 1M, managed fine-tuning per training token, and dedicated NVIDIA GPUs from $8.00/hr. $1 free credits, self-serve, no cold starts.
- GitHub Copilot: GitHub's AI coding assistant with agent mode and MCP support across 6 IDEs, plus a free plan with no credit card required.
- Vertex AI: Google Cloud's Vertex AI, renamed Gemini Enterprise Agent Platform in April 2026: Gemini and Claude by API, GPU and TPU training, agent hosting, 39 regions.
- Groq: Fast open-model inference, now built on NVIDIA-licensed LPU hardware
- Hetzner: Hetzner sells cloud VPS, dedicated and GPU servers and S3-compatible object storage from Germany, Finland, the US and Singapore, with a large traffic allowance on EU cloud plans.
- Kimi K3: 2.8T-parameter open-weight MoE model from Moonshot AI (July 2026) with a 1M-token context window and the top published open-weight result on GPQA Diamond.
- SambaNova: SambaNova Systems, founded 2017, builds custom RDU chips for AI inference. Raised $2.4B+ total; Series F first close at $11B valuation (Jul 2026).
- Tabnine: Enterprise AI coding assistant with privacy-first architecture, agentic workflows, and flexible deployment
- Together AI: The AI Native Cloud: a full-stack platform for training, fine-tuning, and deploying open-source AI models
Sources
Still deciding?
This guide covers a handful of options. Smart Match checks every listing in the directory against how you actually work and what you can spend, then hands you the shortlist and the reason behind each pick.
Find your toolsRelated guides
- What Happened When 7 AI Agents Got Real Bank Accounts and No SupervisionAnalysisWhat changed and who it affects
- AI Development Services in 2026: Which Layer You Actually NeedBuyer's guideHow to pick, across a category
- Algolia and You.com Both Call Themselves AI Search Infrastructure. They Aren't Rivals.ComparisonHead-to-head, with a verdict
- Attio vs HubSpot in 2026: Which CRM for a Startup?ComparisonHead-to-head, with a verdict
- Best AI Agent Builders in 2026: Automate, Build or Self-HostBuyer's guideHow to pick, across a category
- Best Autonomous AI Agents in 2026: How Much Control to Hand OverBuyer's guideHow to pick, across a category