Last updated: 2026-09-06
Groq is an AI inference cloud serving more than 6 million developers, running open-weight models such as Llama, Qwen, and GPT-OSS on Language Processing Unit (LPU) hardware that NVIDIA now manufactures under license as the Groq 3 LPX chip, for deterministic, low-latency production inference.
About Groq
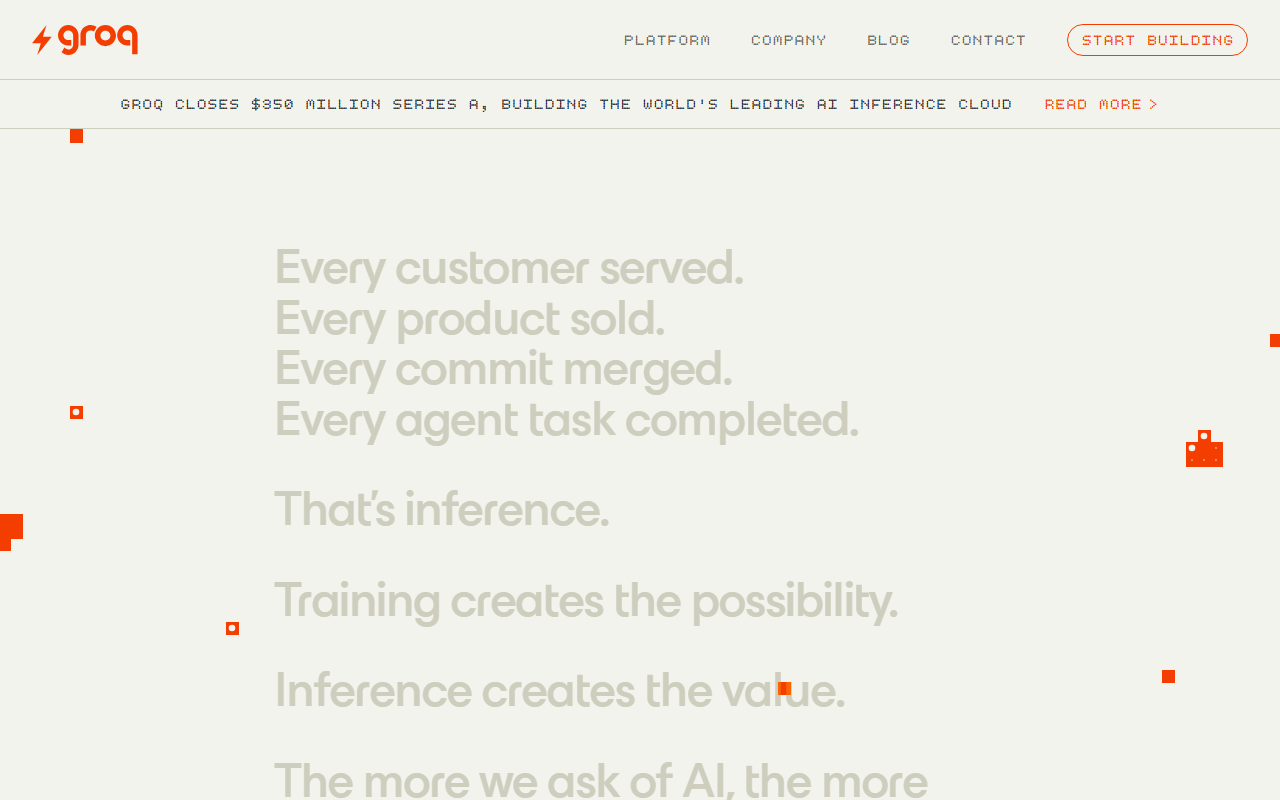
Groq is an AI inference platform founded in 2016 by former Google TPU engineer Jonathan Ross, built around a proprietary Language Processing Unit (LPU) chip designed to outrun GPU-based inference on throughput and latency. In December 2025, Groq granted NVIDIA a non-exclusive license to that inference technology; Ross and Groq president Sunny Madra moved to NVIDIA as part of the deal, and Simon Edwards became Groq's CEO. NVIDIA has since begun shipping the licensed design as the NVIDIA Groq 3 LPX chip, and Groq itself now deploys that hardware, alongside NVIDIA's Vera Rubin NVL72 systems, across its own data centers rather than fabricating further LPU silicon in-house.
9 billion valuation it held a year earlier, to fund an expansion from roughly 54 MW to more than 200 MW of AI compute capacity across its 13 global data centers by 2027. GroqCloud, the developer API, has continued operating without interruption throughout the transition, remains fully OpenAI API compatible, and serves more than 6 million developers and enterprise clients including the McLaren F1 Team.
Screenshots
Pricing
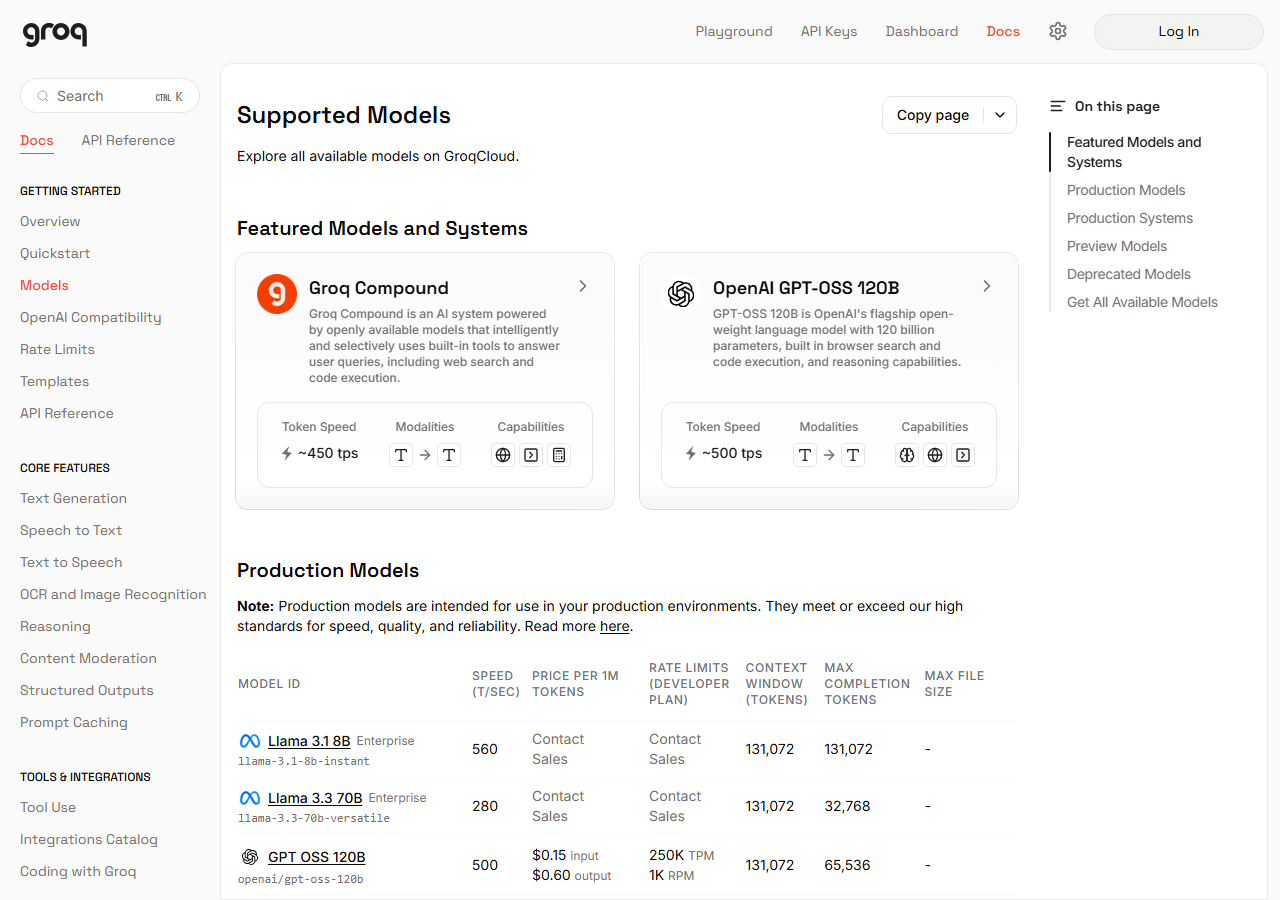
3 70B moved to Enterprise-only in August 2026). 04/hour; Batch API cuts eligible rates by 50 percent. 3 70B, and dedicated capacity, contact sales.
| Tier | Monthly price | What it includes |
|---|---|---|
| Free | Free | Rate-limited free access to GPT-OSS, Whisper, and Qwen models, no card required. 3 70B are no longer available on this tier as of August 2026 (Enterprise-only). |
| Developer (Pay-as-You-Go) | Free | 3 70B moved to Enterprise-only in August 2026. |
| Enterprise | Free | Custom pricing for Llama 3.1 8B, Llama 3.3 70B, and dedicated capacity; scalable capacity; dedicated support; LoRA inference; SSO & SCIM; 90-day audit log retention; contact sales for pricing |
| Llama 3.3 70B Versatile | Free | Enterprise-only as of August 2026, contact sales; no longer on the public Developer pay-as-you-go tier. |
| Llama 3.1 8B Instant | Free | Enterprise-only as of August 2026, contact sales; no longer on the public Developer pay-as-you-go tier. |
| GPT-OSS 120B | Free | 60 per 1M output tokens; now the highest-throughput model available outside Enterprise contact-sales pricing. |
| GPT-OSS 20B | Free | 30 per 1M output tokens; smaller, faster sibling of GPT-OSS 120B for latency-sensitive workloads. |
| Whisper Speech-to-Text | Free | 04 per hour; billed per hour transcribed, not per token. |
Feature Comparison by Tier
| Feature | Free | Enterprise | Developer (Pay-as-You-Go) |
|---|---|---|---|
| Llama 3.1 8B / 3.3 70B access | — | Contact sales | — |
| GPT-OSS 120B / 20B access | Rate-limited | Custom pricing | $0.075-$0.60 per 1M tokens |
| Whisper speech-to-text | Rate-limited | Custom pricing | $0.04-$0.111 / hour |
| Batch API discount | — | Negotiated | 50% off eligible models |
| Zero Data Retention (self-serve) | Yes | Yes, plus SSO/SCIM | Yes |
| On-prem GroqRack deployment | — | Yes | — |
| Support | Community Discord | Dedicated support | Chat support |
Key Features
- NVIDIA-Licensed LPU Hardware: Groq's Language Processing Unit design is now built and shipped by NVIDIA as the Groq 3 LPX chip under a technology-licensing deal, continuing the SRAM-centric, deterministic inference architecture Groq originally designed in-house.
- OpenAI Compatible API: Drop-in replacement for OpenAI's API; integrate with two lines of code by changing the base_url and API key.
- Multi-Model Catalog, Minus Two Flagships: GPT-OSS and Whisper speech-to-text models remain on the public API, but Groq's two most-used Llama models moved to Enterprise-only contact-sales pricing in August 2026.
- Sub-Second Latency: GroqCloud's own benchmark page shows its fastest hosted model returning several hundred tokens per second, keeping response times predictable under real-world load.
- Built-In Tools & Compound AI: Native web search, code execution, browser automation, and MCP integrations power the Groq Compound and Compound Mini systems for agent-based applications.
- Enterprise-Grade Compliance & Data Controls: SOC 2, GDPR, and HIPAA compliant, with self-serve Zero Data Retention available in the console's Data Controls and an on-premises GroqRack deployment option.
Pros
- Still among the fastest hosted inference options for open-weight models, even after its LPU design became an NVIDIA-licensed chip
- GPT-OSS per-token pricing undercuts most GPU-hosted APIs for comparable open-weight models, with no minimum spend
- OpenAI API compatibility makes migration a two-line change (base_url and key) for most existing projects
- Self-serve Zero Data Retention removes a step that competitors still gate behind an enterprise sales call
Cons
- Groq's two most-cited open-weight Llama models now require an Enterprise sales conversation instead of public per-token pricing, since they moved off self-serve access in August 2026
- Founder/CEO Jonathan Ross and president Sunny Madra left for NVIDIA under the technology-licensing deal, adding leadership turnover for buyers evaluating long-term roadmap stability
- Limited to open-source models; no proprietary frontier models like GPT-4 or Claude
- Output tokens are billed at a higher rate than input tokens on every remaining public tier
Product Information
- Cloud
- Yes
- Self-Hosted
- No
- On-Premise
- Yes
- Languages
- English
- Training
- Documentation, GroqCloud API Cookbook (GitHub), Discord Community
Data Handling
- Training-data policy
- Does not use customer inference inputs or outputs to train or fine-tune models by default; inference logs are kept up to 30 days for reliability and abuse monitoring unless self-serve Zero Data Retention is enabled in the console's Data Controls.
- Data retention
- 30 days
- Compliance
- SOC 2 · GDPR · HIPAA compliant
Frequently Asked Questions
What does Groq actually cost?
On the Developer pay-as-you-go tier, GPT-OSS 120B runs $0.15 per 1M input tokens and $0.60 output, while the smaller GPT-OSS 20B costs $0.075 input and $0.30 output. Whisper Large V3 transcription is billed at $0.111 per hour of audio, and the faster Whisper Large V3 Turbo at $0.04 per hour. The Batch API cuts eligible rates by 50 percent for workloads that can wait, and Enterprise customers get custom volume pricing, which is now the only way to access Llama 3.1 8B and Llama 3.3 70B since Groq moved those two models behind a sales conversation.
Can you use Groq without paying?
Yes. The free tier needs no credit card and gives rate-limited access to GPT-OSS, Whisper, and Qwen models. The two Llama models that used to carry generous free daily request caps are no longer included on the free or Developer tiers; reaching them now requires an Enterprise plan.
What are Groq's closest competitors?
Together AI and Fireworks AI are the two most direct competitors for hosted open-weight model inference. Replicate is a third option if you would rather manage your own model hosting on general-purpose GPU infrastructure instead of a managed inference API.
How does Groq compare to Together AI in 2026?
Groq still wins on raw latency for the open-weight models both platforms host, running on the same lineage of LPU-derived hardware that NVIDIA now manufactures under license from Groq. Together AI counters with a broader model catalog and native fine-tuning support, which Groq does not offer at all. Teams chasing the fastest possible response time pick Groq; teams that need to customize or fine-tune a model pick Together AI.
How do you set up Groq?
Create a free account at console.groq.com to get an API key. Because Groq is fully OpenAI API compatible, existing OpenAI SDK projects can switch over by changing the base URL and key, usually in under ten minutes. New users can test models directly in the GroqCloud playground before writing any code.
Top Alternatives
- Together AI: Pick Groq if you need the lowest possible latency on open-weight models; pick Together AI if you want a wider catalog and native fine-tuning, which Groq still does not offer.
- Fireworks AI: Pick Groq for raw inference throughput; pick Fireworks AI if you want compound AI systems with function calling built in as the core product.
- Replicate: Pick Groq for a managed inference cloud with nothing to configure; pick Replicate if you need to deploy and version arbitrary custom models on your own GPU infrastructure.
HokAI guides covering Groq
- Groq's Llama Pricing Just Went Enterprise-Only. Where Does That Leave Fireworks AI?: Groq moved Llama to Enterprise-only pricing in Sept. 2026. Compare real speed, cost, and fine-tuning against Fireworks AI before choosing an inference API.
- Best Generative AI Infrastructure in 2026: 7 Platforms, Three Separate Decisions: Fireworks AI, Together AI, Groq, Modal, Replicate, Archil and Cast.ai compared on price and speed, plus the storage and cost layers most 2026 roundups skip.
- Fireworks AI vs Together AI: Which Should You Use in 2026?: Fireworks and Together AI now charge the identical per-token rate on DeepSeek V4 Pro, so price no longer separates these two open-model inference platforms.
- How to Choose the Right LLM: A Practical Guide to GPT, Claude, Gemini, Llama, DeepSeek, and Perplexity: Choosing an LLM in August 2026 means new GPT-5.6 pricing, an expiring Claude Sonnet 5 discount, and Meta exiting open-weight models. This guide has the numbers.