Best Generative AI Infrastructure in 2026: 7 Platforms, Three Separate Decisions
The best generative AI infrastructure choice depends on workload: Groq offers the fastest published per-token pricing on a short model list, Together AI has the widest open-model catalog after its $800M Series C, Fireworks AI covers dedicated GPUs from H100 at $8 an hour to GB300 at $20, and Modal or Replicate suit custom compute over hosted chat APIs.
The short version
Generative AI infra in 2026 splits into three buys: inference APIs (Fireworks, Together, Groq), raw GPU rental (Modal, Replicate), and the storage plus cost layer underneath (Archil, Cast.ai). Re-read on 7 November 2026, the lineup holds while prices moved: Fireworks GPU tiers rose on September 1 and Archil restructured its plans.
Not sure which one fits you? Describe your situation and Smart Match names three tools.Find my AI tools
In this guide12 sections
Fireworks AI's September 1 GPU price rise has taken effect: an on-demand H100 hour now costs $8, up from $7. We re-read every platform on this list on 7 November 2026.
That is the pattern worth planning around. Gemini 3.8 Flash doubles its paid rate on January 1, 2027, per Google's pricing page. Crusoe's page lists a new on-demand rate card starting December 1, 2026. Inference platforms are repricing as GPU availability shifts, so the real question is not "which platform is cheapest this week."
For a startup about to sign a monthly compute contract, it is which of three separate infrastructure decisions you are actually making: renting inference by the token, renting GPUs by the hour, or paying for the storage and cost-management layer that sits underneath both. Most buyer's guides collapse all three into one ranked list. That is why they miss half the stack.
If you would rather answer a few questions and get a shortlist, Smart Match does that across the whole catalog.
- Fireworks on-demand H100, per hour
- $8
- Was $7 before September 1
- Together on-demand HGX H100, per GPU-hour
- $3.99
- Cluster rate card
- Modal B300, per second
- $0.001972
- Same as our August read
- Archil Developer monthly minimum
- $10
- Plans restructured since August
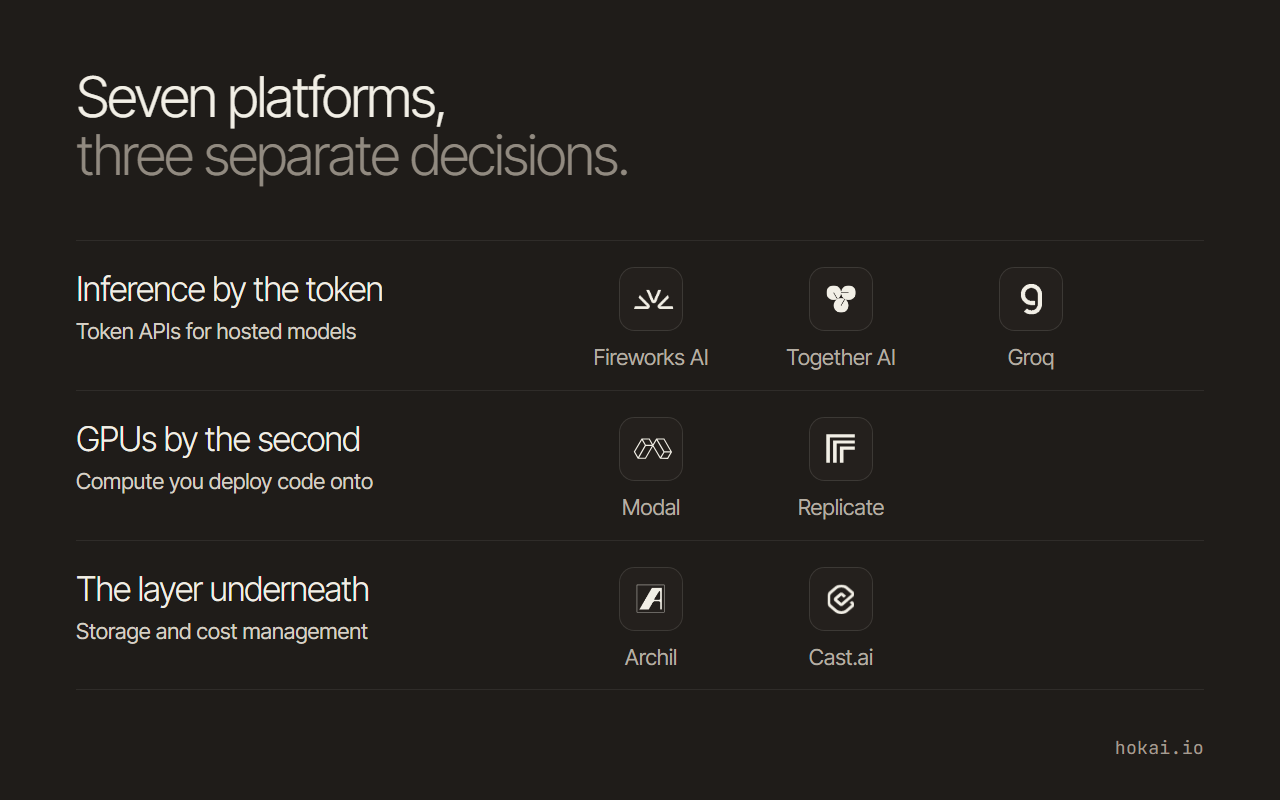 Hokai chart of the three separate infrastructure decisions in this guide and the platforms shortlisted for each, from the vendors' pricing pages as re-read on 7 Nov 2026.
What changed since 18 August 2026
Re-checked 7 November 2026: the lineup holds. Every pick was re-read on its own pricing page, and these details moved.
| Platform | What moved | Now |
|---|---|---|
| Fireworks AI | September 1 GPU increase took effect; "$1 free credits" line gone | H100 $8/hr, B200 $13/hr |
| Archil | Plans restructured around hard caps and monthly minimums | Free, $10 and $500 tiers |
| Modal | Team now includes $100 a month of credit | Team $250 + compute |
| Groq | Preview Qwen entry is now Qwen3.8-27B | GPT OSS prices unchanged |
| Google AI Studio | Free tier covers Gemini 3.8 Flash and 3.5 Flash-Lite | 2.5-generation models off the page |
| Cast.ai | Homepage headlines 50 to 80 percent lower costs | Still quote-only |
| Replicate | Nothing | H100 $5.49/hr |
Challengers considered are in the table further down. None beat the weakest pick in its job on the evidence we could read, so none replaced a pick.
How to choose: four criteria that hold regardless of which vendor wins this quarter
Workload shape. If you are calling a chat or completion endpoint against a model someone else hosts, you want a token API: Fireworks AI, Together AI, or Groq. If you are running your own code, custom pipelines, or fine-tuning jobs that need arbitrary compute, you want raw GPU rental: Modal or Replicate. Conflating the two is the single most common overspend in this category: teams rent GPUs by the hour for a workload that a $0.15-per-million-token API would have served for a fraction of the cost.
Speed versus catalog breadth. Groq's GPT OSS 120B model runs at about 500 tokens per second, according to GroqCloud's own model documentation. That is fast. It is also a short production list, not the catalog Together AI offers. Pick speed when the product experience depends on latency; pick breadth when you need a specific fine-tuned or open-weight model nobody else hosts.
Storage and state. Agent frameworks that write files, run sandboxed code, or maintain session state need a durable filesystem underneath the inference call. Almost no roundup budgets for this layer, and it is usually the first thing that breaks: a sandbox fills its ephemeral disk mid-run, or a multi-step agent loses state between calls because nobody provisioned real storage.
Cost management at scale. Once GPU spend moves onto your own Kubernetes cluster, the buying decision changes again. You are no longer choosing an inference vendor. You are choosing a tool to stop overpaying for the GPUs you already provisioned.
The shortlist: token APIs
Fireworks AI charges per token for serverless inference, with usage drawing down prepaid credits and no commitment. For dedicated capacity it bills per GPU-second, with no charge for start-up time. Its pricing page also lists a Reserved Throughput plan with a 99.9 percent uptime term for steady production traffic.
- Serverless: from $0.05 per million input tokens.
- On-demand GPUs: H100 and H200 at $8 an hour, B200 at $13, B300 at $15, GB300 at $20.
- The caveat: every on-demand tier was raised on September 1, 2026 (our August read had the H100 at $7 and the B200 at $10), and region-restricted deployments are priced at 1.5 times.
Together AI hosts a large catalog of open models. It closed an $800 million Series C on July 1, 2026, led by Aramco Ventures, according to its own announcement, which also reports annual bookings above one billion dollars.
- Tokens: MiniMax M3.1 Flash at $0.15 input and $0.60 output per million; Muse Spark Open at $1.25 and $4.25.
- GPU Clusters, on-demand per GPU-hour: H100 $3.99, H200 $5.99, B200 $8.19, B300 $9.99.
- The caveat: separate rate cards for tokens, dedicated endpoints and clusters mean working out the real bill for one workload takes spreadsheet time.
IBM signed a separate $240 million multi-year deal with Together in August to build an Nvidia HGX B300 inference cluster on IBM Cloud, per IBM's newsroom, with availability targeted for Q1 2027.
Groq runs on custom LPU silicon rather than GPUs, and its marketing site carries no pricing table at all. The real numbers live in GroqCloud's model documentation. It is not the only custom-silicon inference vendor: SambaNova builds its own RDU chips for inference, according to its Hokai record.
- GPT OSS 20B: 1,000 tokens per second at $0.075 input and $0.30 output per million.
- GPT OSS 120B: about 500 tokens per second at $0.15 input and $0.60 output.
- The caveat: the production list is short, and Groq marks the newer entries, including Qwen3.8-27B, as preview-only and subject to discontinuation at short notice.
The shortlist: compute, storage, and cost tools
Modal bills GPU compute per second with no charge for idle time. This is infrastructure for running your own code, not a hosted chat API.
- Rates: from $0.000164/sec for an Nvidia T4 up to $0.001972/sec for a B300.
- Starter: $0 plus compute, with $30 a month in credits, 3 seats and 10 GPUs of concurrency.
- Team: $250 a month plus compute, with $100 of credits, unlimited seats and 50 concurrent GPUs.
- The caveat: there is a real integration cost before the first token comes back.
 Modal's pricing page, captured 18 Aug 2026; the per-second rates shown here were unchanged when we re-read the page on 7 Nov 2026.
Replicate is the simplest onramp to a single hosted open model: pay per run for public models, or pay hardware time for private deployments.
- Public models: FLUX Pro at $0.04 per output image.
- Hardware: from $0.81/hour on a T4 to $5.49/hour on an H100.
- The caveat: the pricing page lists no free tier, so there is no equivalent of Modal's monthly credit or Archil's no-card Free plan.
Archil turns an S3 bucket into a POSIX filesystem for AI agent sandboxes. Its plans were restructured since our August read.
- Free: no credit card, hard-capped at 5 file systems, 1,000 tool calls and 1 hour of sandboxes.
- Developer: $10 monthly minimum. Team: $500 monthly minimum, 25,000 file systems and 250 concurrent sandboxes.
- Usage: $0.20 per GiB-month of active storage, $0.05 per 1,000 tool calls, $0.055 per vCPU-hour.
- The caveat: minimums are billed as floors, so on Developer $6 of usage is invoiced as $10.
Cast.ai automates Kubernetes rightsizing and spot-instance management. Its homepage headlines 50 to 80 percent lower Kubernetes costs, from a customer story about Banking Circle. The caveat, and it is a real one: Cast.ai publishes no self-serve pricing. Every quote requires a form and a conversation about your environment.
Which one, for which bottleneck
| Bottleneck | Pick | Price (7 Nov 2026) | The one caveat |
|---|---|---|---|
| Lowest latency at a defensible price | Groq | $0.075-$0.60 per 1M tokens | Short, curated model list |
| Widest open-model catalog | Together AI | $0.15 to $4.25 per 1M (sampled) | Three separate rate cards |
| Raw GPU-second billing | Modal | $0.000164 to $0.001972/sec | Needs deployment code |
| Simplest onramp to one hosted model | Replicate | $5.49/hr (H100) or per run | No free tier |
| Durable storage under agent sandboxes | Archil | Free, then $10 or $500 minimum | Minimum billed as a floor |
| Cutting a Kubernetes GPU bill | Cast.ai | Custom quote only | No self-serve pricing |
| Dedicated GPUs on a token platform | Fireworks AI | $8/hr (H100) to $20/hr (GB300) | Rates rose September 1 |
Fireworks, Together, and Groq: the three people actually cross-shop
Most buyers narrow the token-API decision to these three, and the honest answer is that none of them wins outright. Fireworks offers the widest range of dedicated GPU classes of the three, from H100 through GB300, plus Reserved Throughput with an uptime term.
Together wins on catalog size and on the credibility that its Series C and an IBM enterprise contract buy. It is also the cheapest of the three on posted on-demand H100 hours, as the key numbers above show. Groq wins on speed-per-dollar for the models it hosts, but it will not serve a niche fine-tuned checkpoint the way Together or Fireworks can.
For a four-person team building a customer-facing chat feature where response latency drives conversion, Groq is the right default. For a team that needs a specific open-weight model, or wants the reassurance of a vendor IBM just wrote a $240 million check to scale, Together is the safer pick. Fireworks sits between them: broader dedicated-GPU access than Groq, and a rate card that has already absorbed its September increase, which makes it a known quantity for a contract signed today.
Challengers we checked on 7 November 2026
A challenger takes a spot only if it beats the weakest pick in its job on dated evidence. These were read on the vendor's own pages this run.
| Candidate | Job | What we read | Beats a pick? |
|---|---|---|---|
| Baseten | Token APIs, dedicated inference | H100 $6.50/hr, B200 $9.98/hr, per-token model pricing | No: no speed or catalog edge shown |
| Crusoe | GPU rental | Hourly rates per GPU, new rate card from Dec 1 | No: a GPU cloud, not a per-second onramp |
| CoreWeave | GPU rental | HGX B200 8-GPU instance $68.80/hr ($8.60 per GPU) | No: instance billing at cluster scale |
| Daytona | Agent storage and state | $0.0504 per vCPU-hour, 5 free GiB storage | No: a sandbox runtime, not a durable filesystem |
| Kubecost, DevZero, nOps | Kubernetes costs | Vendor-authored comparisons only | No: no independent, dated evidence |
Two other catalog entries, Pipeshift and Luminal, sell managed inference; neither published a rate we could read against the token-API picks, so they stay off the shortlist. Hetzner sells GPU servers and S3-compatible object storage, according to its Hokai record, and is worth a look if you want rented hardware without a cloud platform. For the retrieval and vector side of the stack, see our retrieval infrastructure guide, and browse the whole category in the generative AI infrastructure directory.
Data handling, security and compliance: what we could verify
Pricing pages say little about where your data goes, and we only record what a vendor's own page states. Check each vendor's trust center before sending production or customer data.
- Modal: the Enterprise plan lists audit logs, Okta SSO and HIPAA support; Starter and Team do not.
- Archil: SOC 2 is listed on the Team plan; Free and Developer do not list it.
- Fireworks AI: Sovereign, in private preview for Enterprise, runs inference on GPUs in your own cloud account or data center so that handling stays inside your boundary.
A fourth vendor states its position on the pricing page itself, and four others say nothing there.
- Google Gemini API: the paid tier card states that content is not used to improve Google's products, and the free-tier card does not list that.
- Groq, Together AI, Replicate, Cast.ai: we found no data-handling terms on the pricing pages we read, so we make no claim.
The plumbing nobody budgets for
Two categories of spend get discovered after the contract is signed, not before.
The first is storage. An agent that writes intermediate files, checkpoints a long-running task, or shares state across sub-agents needs somewhere durable to put that data, and ephemeral container storage is not it. Archil's pitch, mounting an S3 bucket as a POSIX filesystem that outlives any single sandbox, answers a problem most teams do not see until an agent demo fails mid-run because the disk filled up.
Baseten and Daytona now price sandboxes too, which tells you the category is filling in. But a sandbox with a small disk is not the same purchase as a filesystem that outlives it. None of the competing buyer's guides for this category, including the ones ranking above Hokai for these terms, mention a storage-layer product at all.
The second is cost management once you are big enough to run your own Kubernetes cluster instead of renting someone else's API. That is a genuinely different job from picking an inference vendor. Cast.ai's pitch is that most teams over-provision GPU nodes and leave spot-instance savings on the table.
There is no way to verify its headline number against a published, itemized source, and Cast.ai's own pricing page requires a sales conversation to get a quote at all. It belongs on this list anyway, because a reader who has scaled past the token-API stage and hit a six-figure GPU bill needs to know this category of tool exists, even with the caveat attached.
Who should skip this category entirely
Not every reader needs any of the above. Google AI Studio has a free tier on Google's Gemini API pricing page that charges nothing for input or output tokens on Gemini 3.8 Flash and 3.5 Flash-Lite. A team validating a product idea before committing to a paid contract should prototype there first and graduate to a paid platform only once the free tier's limits actually bind.
The paid tier of Gemini 3.8 Flash is scheduled to double on January 1, 2027, so budget for it. Google's pricing page lists these rates per million tokens:
| Period | Input | Output |
|---|---|---|
| Through Dec 31, 2026 | $0.75 | $3.75 |
| From Jan 1, 2027 | $1.50 | $7.50 |
A prototype that is cheap in December can double in cost in January without a single line of code changing, which is exactly the sort of drift a fixed monthly contract should be checked against.
At the other end, Supermicro is not a rental decision at all. It sells the physical hardware: its Nvidia GB300-based Super AI Station is rated at 20 petaflops of FP4 performance with 252GB of HBM3e GPU memory, per the company's own product announcement. Its fiscal Q2 2026 filing reported $12.7 billion in net sales, up 123 percent year over year.
That filing is not its latest: Supermicro published first-quarter fiscal 2027 results on its investor site on November 3, 2026, which we did not read, so treat the Q2 figure as a dated snapshot. The on-prem route is relevant only to teams building their own data center, not comparing cloud vendors.
And Tamarind Bio shows how far this category's edges stretch: it hosts more than 200 specialized biology models, including AlphaFold and RFdiffusion, for protein and drug-discovery research, and raised a $13.6 million Series A led by Dimension Capital in February 2026, according to the company's own blog. Its pricing is not published anywhere in this research. A biotech research team is the only reader for whom this entry belongs on a shortlist at all.
The obvious objection
The case against everything above is simple: compute is a commodity, so just take this week's cheapest per-token rate and move on. Rates converge over time, the argument goes, so optimizing today's number is a waste of a decision-making cycle better spent building the product.
That argument does not survive the price lists above. A vendor is not required to hold a rate steady: Fireworks raised every GPU tier on September 1, Google has scheduled a doubling of Gemini 3.8 Flash's paid rate for January 1, and Crusoe has a new rate card starting December 1. "Cheapest this week" is not "cheapest this quarter," and a contract signed on today's number can look expensive by spring.
There is also a real migration cost the commodity argument ignores: a model deployed against one platform's serving stack, with its own tokenizer quirks and quantization support, does not move to a competitor for free. Chasing a small per-token delta across vendors often costs more in engineering time than the delta itself saves.
What would change this
None of the platforms we read collapse all three buckets, inference, GPU rental, and storage-plus-cost-management, into one bill with no material trade-off. Modal comes closest on compute and storage; Together comes closest on inference and GPU clusters. Neither owns the Kubernetes cost-optimization layer Cast.ai occupies. If a single vendor genuinely merged all four into one contract with no compromise on any axis, this three-bucket framework would stop being useful, and nothing in this research suggests that is close.
Watch the Blackwell rate cards. Fireworks charges $13 an hour for a B200, and Together lists on-demand HGX B200 at $8.19. If that gap closes, or Fireworks cuts its rate, that is reason enough to reopen a contract signed this month.
Frequently asked questions
What is the best generative AI infrastructure platform in 2026?
There is no single winner because inference APIs, GPU rental and storage are three different purchases. As of 7 November 2026, Groq wins on speed per dollar for its short production model list, Together AI on catalog breadth and vendor backing after its $800 million Series C, and Fireworks AI on dedicated GPU range from H100 to GB300. The right pick depends on whether the workload is a hosted chat call or custom compute.
Is Fireworks AI or Together AI cheaper for LLM inference?
It depends on the model and the mode. Together lists models from $0.15 input and $0.60 output per million tokens, and its on-demand H100 cluster hour is $3.99 against $8 at Fireworks. Fireworks raised every on-demand GPU tier on September 1, 2026, and its serverless rates start at $0.05 per million input tokens. Price your own token mix on both rate cards before choosing.
Do AI agent sandboxes need a separate storage layer?
Yes, once an agent writes files, checkpoints a task or keeps state across steps. Ephemeral container disk does not outlive a sandbox session, which is the gap Archil fills by mounting an S3 bucket as a POSIX filesystem. Its Free plan is hard-capped at 5 file systems and 1,000 tool calls, and paid plans carry $10 and $500 monthly minimums.
How much does GPU rental cost per hour in 2026?
Rates vary by provider and class. Modal bills per second, from $0.000164 for a T4 to $0.001972 for a B300. Replicate charges $5.49 an hour for an H100, Baseten $6.50 and Fireworks $8, while Together lists on-demand HGX H100 at $3.99 per GPU-hour. All figures were read from vendor pages on 7 November 2026.
Is Cast.ai worth it for a small startup's Kubernetes GPU cluster?
Cast.ai targets teams already running their own Kubernetes cluster and overpaying for GPU nodes, not teams calling a hosted inference API. Its homepage headlines 50 to 80 percent lower Kubernetes costs from a customer story, a vendor claim with no independent check, and it publishes no self-serve pricing. It is worth a sales conversation once GPU spend is a real budget line, not before.
Covered in this guide
- Fireworks AI: Enterprise inference platform for open models: serverless tokens from $0.10 per 1M, managed fine-tuning per training token, and dedicated NVIDIA GPUs from $8.00/hr. $1 free credits, self-serve, no cold starts.
- Groq: Fast open-model inference, now built on NVIDIA-licensed LPU hardware
- Archil: A durable shared disk for AI agents that sits on top of your object storage, with serverless sandboxes that bill per tool call and a free tier.
- Baseten: Baseten is an AI inference platform for custom and open-weight models, with a no-fee Basic plan, per-minute GPU billing, SOC 2 Type II and HIPAA.
- Cast.ai: Cast.ai cuts Kubernetes cloud costs 50-70% using automated rightsizing and Spot instance management. Trusted by 2,100+ companies, reached $1B unicorn in 2026.
- CoreWeave: Bare-metal NVIDIA GPU cloud with managed Kubernetes and Slurm, 59 availability zones across the US, Canada and Europe, and free data egress.
- Crusoe: GPU cloud with openly published hourly rates, free network egress, Managed Kubernetes and serverless inference and fine-tuning.
- Daytona: Per-second billed sandboxes for AI agents, in US and EU regions, with GPU and Windows options and $200 of starter credit; the core repo went private in 2026.
- Gemini 3.8 Flash: Google DeepMind shipped Gemini 3.8 Flash on September 2, 2026, a multimodal Gemini 3 model tuned for long-horizon coding and agentic enterprise work.
- Google AI Studio: Free web-based IDE for building, testing, and deploying generative AI applications with Google's Gemini models
- Hetzner: Hetzner sells cloud VPS, dedicated and GPU servers and S3-compatible object storage from Germany, Finland, the US and Singapore, with a large traffic allowance on EU cloud plans.
- Luminal: Serverless and on-prem AI inference from a YC Summer 2025 compiler startup, with an open-source core and a default limit of 60 requests per minute.
- Modal: AI infrastructure that developers love: serverless compute for ML inference, training, and batch processing
- Pipeshift: Managed inference cloud for real-time agents: tuned runtimes, scale-to-zero clusters, multi-region, single-tenant or in your VPC, with no public rate card.
- Replicate: Run open-source AI models via API without managing any GPU infrastructure.
- SambaNova: SambaNova Systems, founded 2017, builds custom RDU chips for AI inference. Raised $2.4B+ total; Series F first close at $11B valuation (Jul 2026).
- Supermicro: Supermicro designs AI server hardware from edge systems (65W TDP) to 8-GPU data center nodes, with $12.68B quarterly revenue and NASDAQ: SMCI listing.
- Tamarind Bio: Hosted platform for AlphaFold, RFdiffusion, Boltz and hundreds of other biology tools via web app, API and MCP, with a Free plan to start on.
- Together AI: The AI Native Cloud: a full-stack platform for training, fine-tuning, and deploying open-source AI models
Sources
Still deciding?
This guide covers a handful of options. Smart Match checks every listing in the directory against how you actually work and what you can spend, then hands you the shortlist and the reason behind each pick.
Find your tools